
EchoMimic
Local AI portrait animation software creates talking-head videos from images and audio, with editable facial landmarks and an Apache 2.0 license.
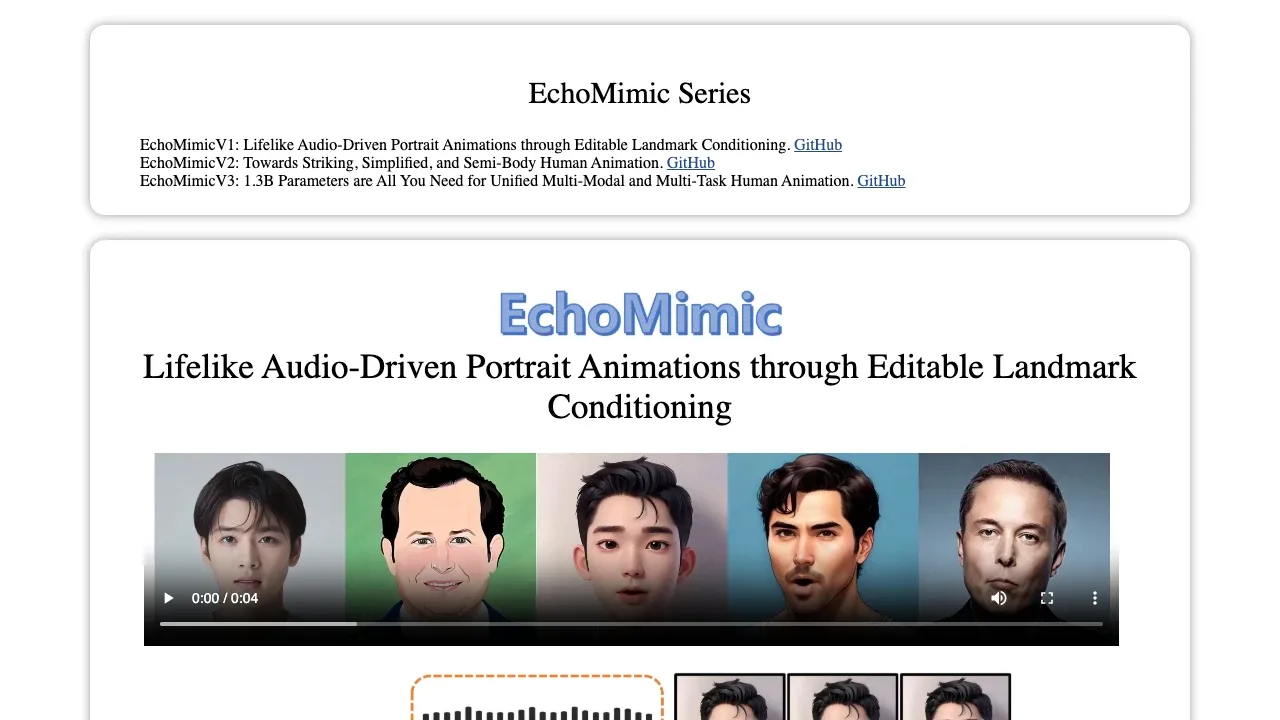
EchoMimic turns a portrait and an audio recording into a talking-head video on your own hardware. It's intended for academic research into speech animation and controlled facial movement.
- Audio-driven animation: Generate portrait videos using pretrained models trained on English and Mandarin Chinese audio.
- Landmark and pose control: Guide facial movement with editable landmarks, pose input, or audio combined with selected landmarks.
- Motion alignment: Match movement between a reference portrait and a driving video.
- Browser interface: A local Gradio interface provides access to generation through a browser, alongside the Python inference tools.
EchoMimic is open source under Apache 2.0. Its tested environments include CentOS and Ubuntu, and it uses NVIDIA GPUs with CUDA. Tested cards include the V100 with 16 GB of VRAM, RTX 4090D with 24 GB and A100 with 80 GB; these configurations aren't stated minimum requirements.
The model components include Stable Diffusion image variations, a VAE and Whisper for audio processing. Accelerated pretrained models are also available.
 Logotyper


