
EvalScope
An open-source LLM evaluation framework tests local models and OpenAI-compatible APIs, with agent benchmarks, load testing and a local dashboard.
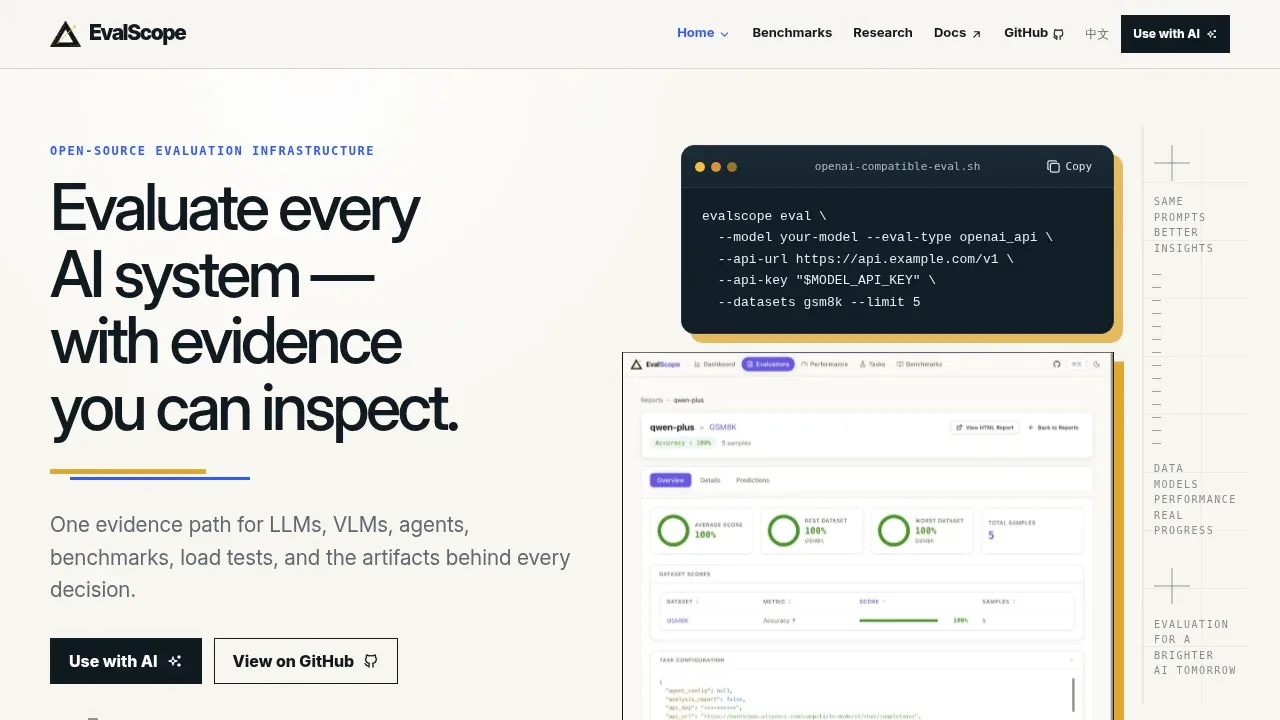
EvalScope is a Python evaluation framework for teams comparing AI models or assessing a model service before deployment. It connects scores to the prompts, predictions and reviews behind them so you can examine individual results.
- Model benchmarks: Evaluate text and vision-language models with MMLU, C-Eval and GSM8K, or use your own datasets and metrics; coverage also includes generated content, embeddings, rerankers and retrieval-augmented generation.
- Agent evaluation: Test multi-turn tasks with tools and a Docker sandbox, then inspect recorded traces for each sample.
- Service load tests: Measure response latency, time to first token and token throughput under concurrent requests, with optional result recording to WandB and SwanLab.
- Model comparison: Use pairwise Arena battles for win rates and rankings, or compare reports and individual predictions in the local web dashboard.
The framework runs locally and evaluates local models or services with an OpenAI-compatible API. API evaluation doesn't require a GPU, but it sends requests to the selected service. Local models can download from ModelScope. Optional evaluation backends include OpenCompass, VLMEvalKit and RAGEval. EvalScope is open source under Apache 2.0.
 Logotyper


