
FastDeploy
A self-hosted LLM and vision-language model toolkit for Linux that provides an OpenAI-compatible API and supports multiple accelerator families.
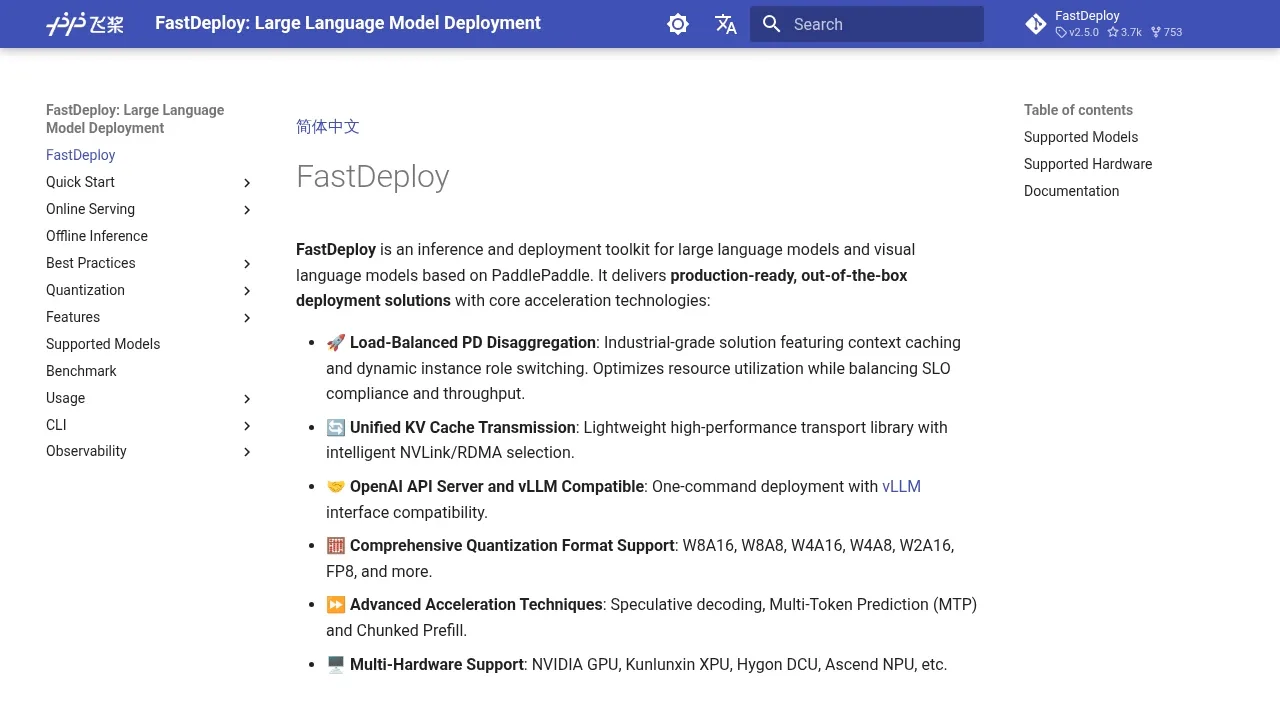
FastDeploy is a self-hosted inference toolkit for teams deploying language and vision-language models on Linux servers. Built on PaddlePaddle, it supports offline inference and online serving.
- Model support: Run ERNIE-4.5, ERNIE-4.5-VL, Qwen3, Qwen-VL, DeepSeek-V3, DeepSeek-R1 and GLM-4.5/4.6 models.
- Application compatibility: Connect applications through an OpenAI-compatible API server or vLLM-compatible interfaces.
- Serving workloads: Separate prompt processing from token generation, balance work across instances and change instance roles dynamically for supported models.
- Inference acceleration: Reuse computation through context and prefix caching, with speculative decoding, multi-token prediction and chunked prompt processing available where supported.
- Quantization: Use reduced-precision formats including W8A16, W4A16, W2A16 and FP8.
FastDeploy is open source under Apache 2.0 and requires Linux. Supported hardware includes NVIDIA GPUs, Kunlunxin XPUs, Hygon DCUs, Iluvatar GPUs, MetaX GPUs and Enflame GCUs. Hardware coverage and acceleration features depend on the model: ERNIE text models support several accelerator families, while the listed ERNIE vision-language models support NVIDIA GPUs. Prefix caching, multi-token prediction and separate prompt processing aren't available for every model.
 Logotyper


