
IndicTrans2
Open-source translation models cover English and India's 22 scheduled languages, with local inference through Hugging Face on a GPU or CPU.
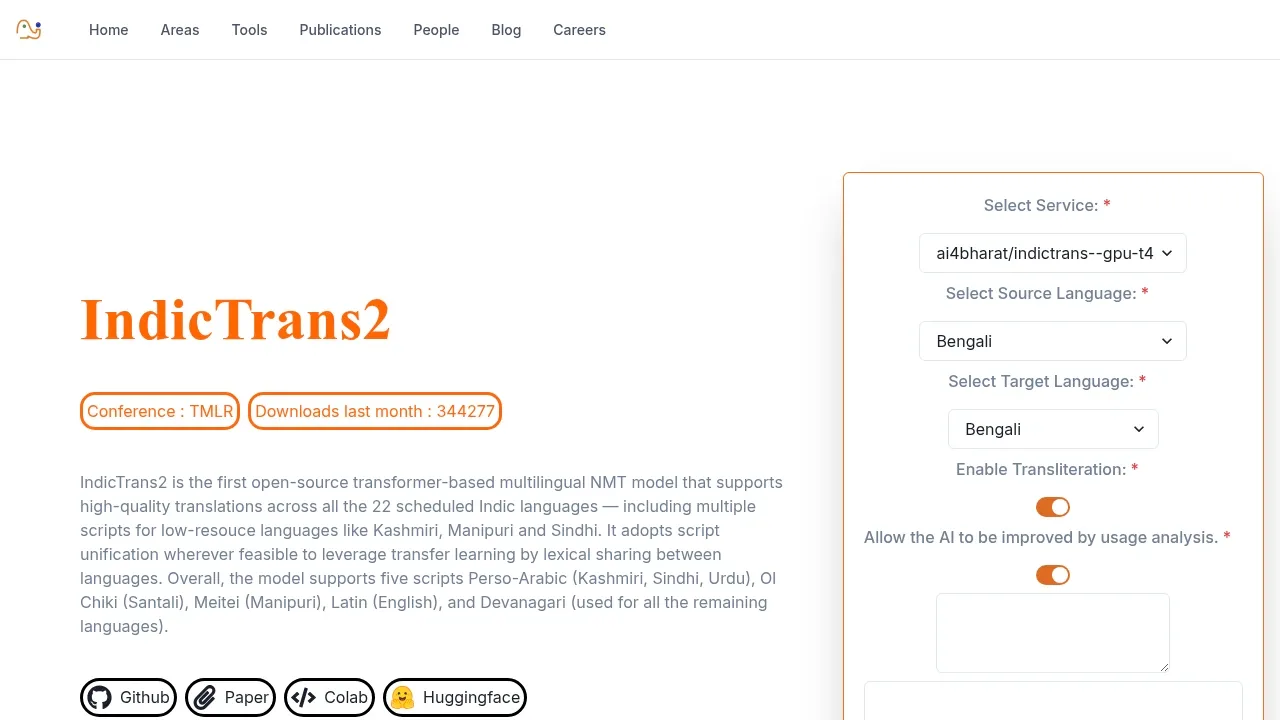
IndicTrans2 is a family of translation models for developers building multilingual applications and researchers working on Indian languages. It covers all 22 scheduled languages of India, including languages with limited training data.
- Translation directions: Translate between English and Indian languages in both directions, or directly between Indian languages.
- Language and script coverage: Work with Hindi, Tamil, Bengali and Bodo, among others, with support for multiple scripts for Kashmiri, Manipuri and Sindhi, plus Ol Chiki for Santali.
- Model choices: Choose base or distilled models through Hugging Face; Fairseq models are also available for English-to-Indic and Indic-to-English translation.
- Training and evaluation: Adapt models with training and fine-tuning code, use the BPCC training dataset, and assess translations with the IN22 general and conversational test sets or the FLORES-22 Indic dev set.
You can run inference on your own hardware through a Python interface. A GPU speeds up translation, and the code can fall back to a CPU. The code repository uses the MIT license. AI4Bharat also provides a hosted browser translation interface that uses an external service rather than your local model.
 Logotyper


