
Jamba
A self-hosted LLM with a 256K context window, vLLM and Transformers support, and research and commercial use under the Jamba Open Model License.
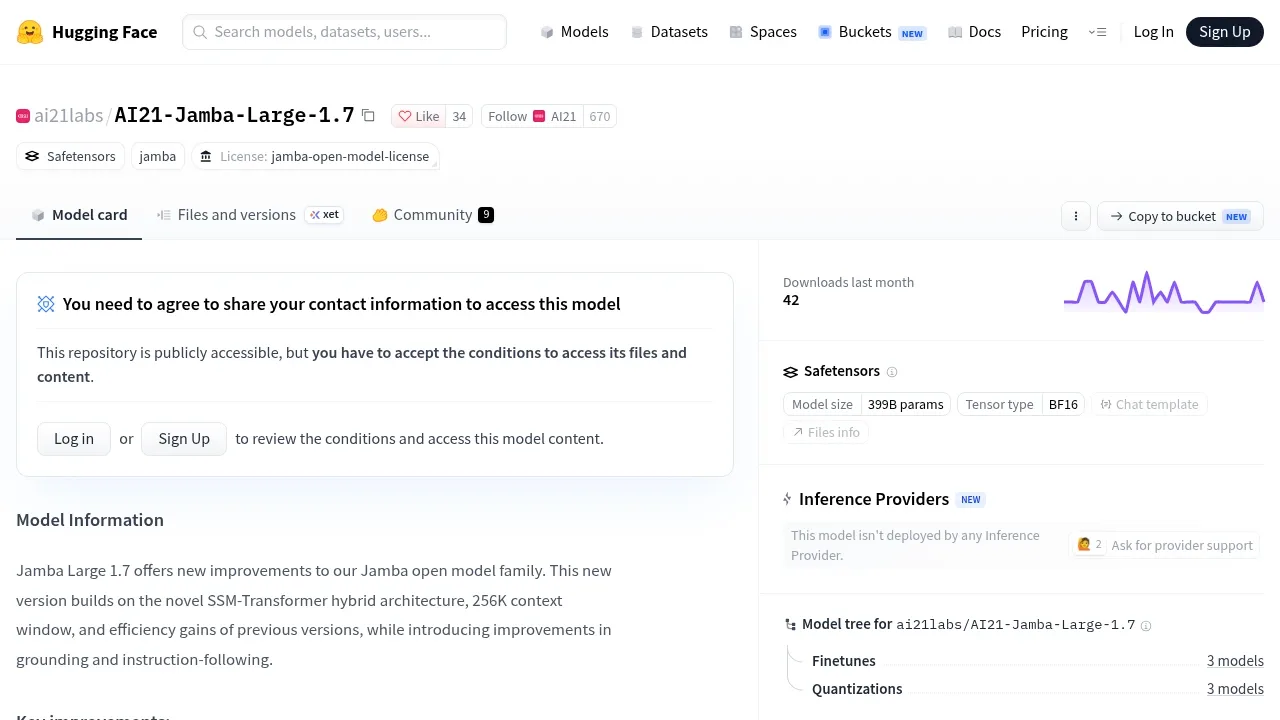
Jamba is AI21's language model family for teams building AI applications on their own servers. The documented Large 1.7 model combines Mamba state-space models with Transformer attention to process long context efficiently. A 256K-token context window makes it relevant for work that depends on lengthy documents, such as investment research, due diligence and reviewing procurement responses.
The model focuses on answers grounded in the material you provide and on following instructions about how to respond. Those traits matter for document-based assistants and customer chatbots that need to stay within supplied context or follow a brand's writing requirements. Other stated uses include drafting medical reports, product descriptions and grant applications, as well as personalized tutoring.
Hardware needs are substantial. The Large model requires quantization to fit on a server with eight GPUs, each with 80GB of memory. It works with vLLM and Hugging Face Transformers; AI21's ExpertsInt8 quantization supports prompts up to 220K tokens on that hardware with the default vLLM configuration. Private deployment runs inference on your own infrastructure. Fine-tuning options include LoRA, qLoRA and full fine-tuning.
The Jamba Open Model License allows research and commercial use under its terms. Access to the model files on Hugging Face requires an account, acceptance of the access conditions and sharing contact information. Supported languages include English, Spanish, French, Portuguese, Italian, Dutch, German, Arabic and Hebrew.


