
Lucebox
A local AI workstation runs large models offline, with an Apache 2.0 inference engine and APIs compatible with OpenAI and Anthropic clients.
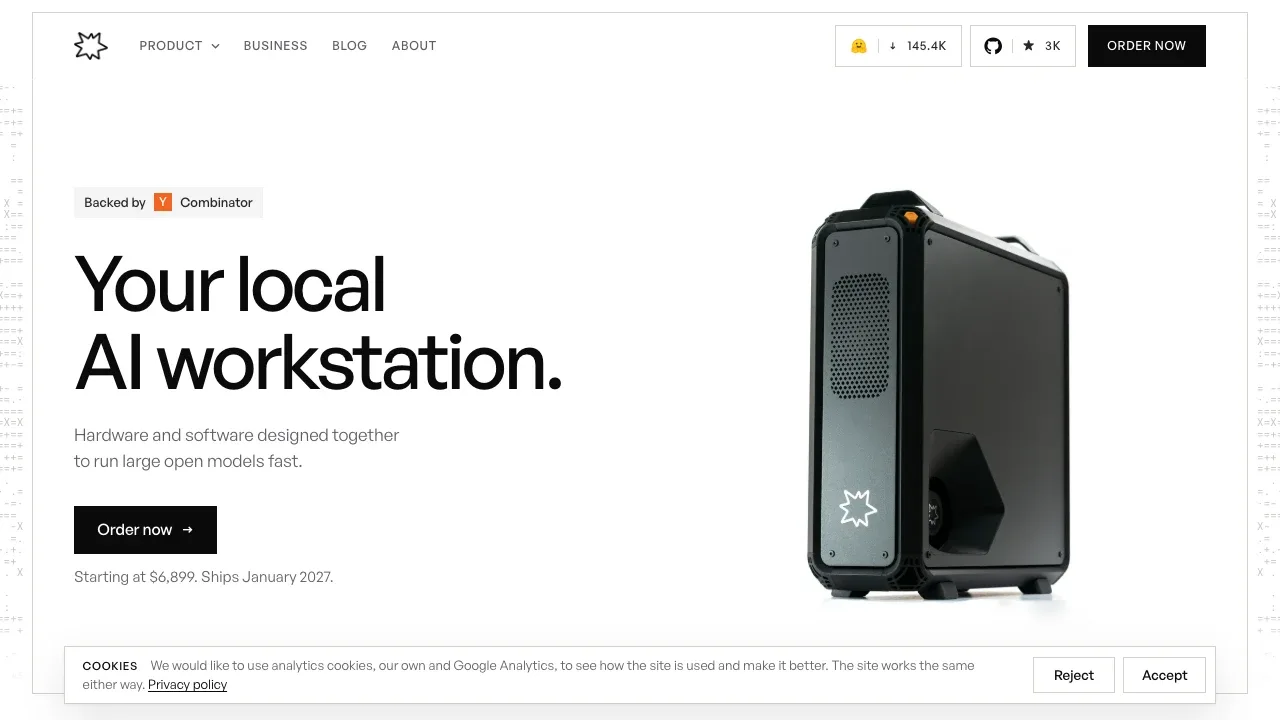
Lucebox is a local AI workstation for developers and teams who want to run models on their own hardware. Its inference engine is also available separately for supported AMD and NVIDIA machines.
- Large model inference: Run DeepSeek V4 Flash and Qwen3.8-27B with hardware-tuned models, or load your own GGUF weights; the workstation can split a model across dedicated GPU memory and unified memory.
- Coding assistant connections: OpenAI-compatible and Anthropic-compatible endpoints let clients such as Claude Code, Codex, OpenCode and Open WebUI use the local server.
- Shared model serving: Serve concurrent users or several agents, and run Qwen and DeepSeek together through one endpoint with Lucebox Mix; available memory limits concurrent long-context workloads.
- Images: The engine accepts image input with supported Qwen and DeepSeek models and generates images with MOSS-Image on the Radeon AI PRO R9700.
The Zero 495 runs Ubuntu Server with AMD ROCm, browser-based management and full root access. It pairs an AMD Ryzen AI MAX+ PRO 495 with 128 GB or 192 GB of unified memory and a Radeon AI PRO R9700 with 32 GB of dedicated memory. The separate engine is free under Apache 2.0, with tested hardware including RTX 3090, RTX 4090, RTX 5090 and AMD Radeon cards; Linux and WSL2 runs are supported.
Inference works fully offline once a model is loaded, keeping local workloads on the machine. Updates and optional cloud fallback need internet access. Optional Tailscale access uses a Tailscale account to reach the private API remotely.
 Logotyper


