
ServiceStack AI Server
A self-hosted AI API gateway that routes requests to Ollama, cloud LLMs and media services, with centralized access controls and usage monitoring.
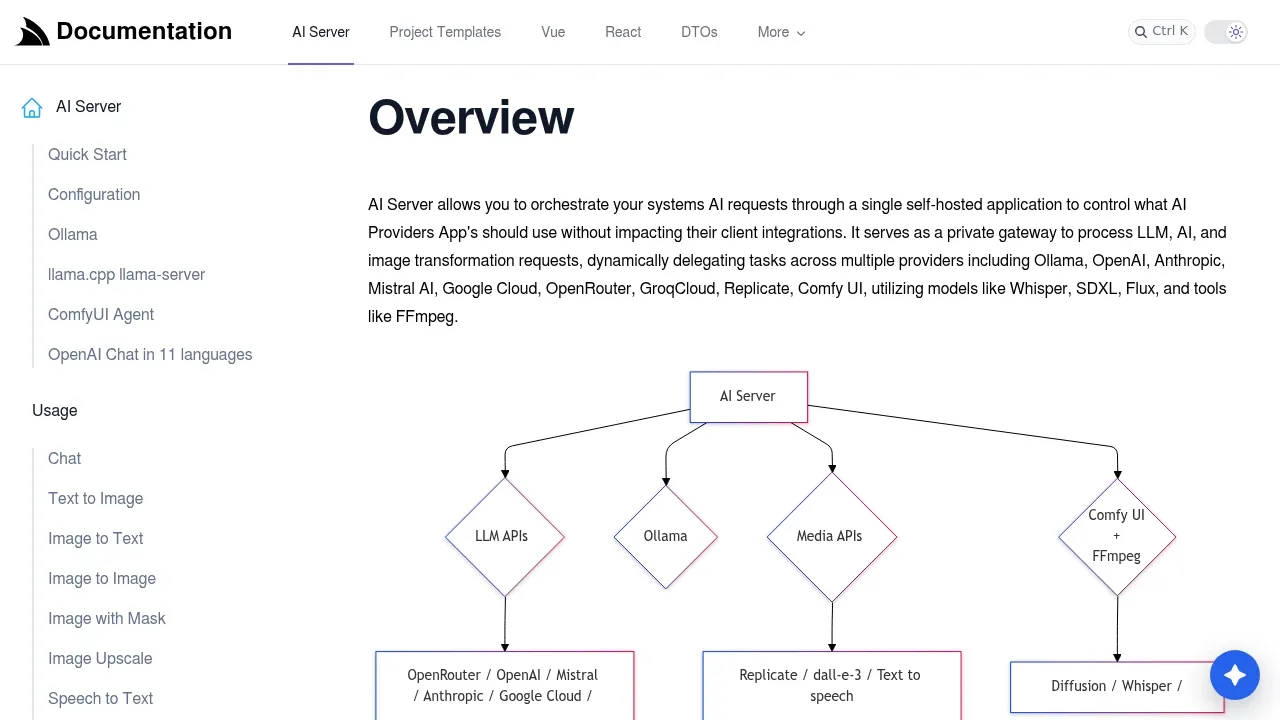
ServiceStack AI Server is a self-hosted gateway for developers and teams whose applications use several AI providers. It runs in a Docker container and gives apps one API integration for local models, cloud LLMs and media processing. Teams can change providers without changing their client integrations.
The gateway runs on your server. Requests sent to local Ollama endpoints or self-hosted media agents use those services; requests routed to OpenAI, Anthropic, Mistral AI, Google Cloud, OpenRouter or GroqCloud go to external providers. Self-hosting the gateway doesn't make cloud processing local.
Its admin interface manages providers, API keys and which models each app can access. It also shows usage statistics, request history and live task progress, plus dashboards for pending, completed and failed background jobs. Teams can distribute requests across multiple providers and keep the gateway behind a firewall.
Media support includes image generation through ComfyUI or services such as Replicate and DALL-E 3, image variations with caching, speech recognition through Whisper, and text-to-speech. FFmpeg agents handle video conversion, scaling and cropping. Optional agents run on GPU servers for media workloads.
Typed client APIs support several programming languages. Built-in storage caches generated assets separately for each API key, and the server archives completed requests in monthly databases.
The application is AGPL-3.0 licensed; ServiceStack framework dependencies have separate license terms. The installer supports Linux, macOS and Windows through WSL2. The optional ComfyUI agent requires a supported NVIDIA GPU on Linux or WSL2, rather than macOS.


