
vLLM Metal
A local LLM serving plugin brings vLLM to Apple Silicon Macs, using MLX for computation and supporting speculative decoding.
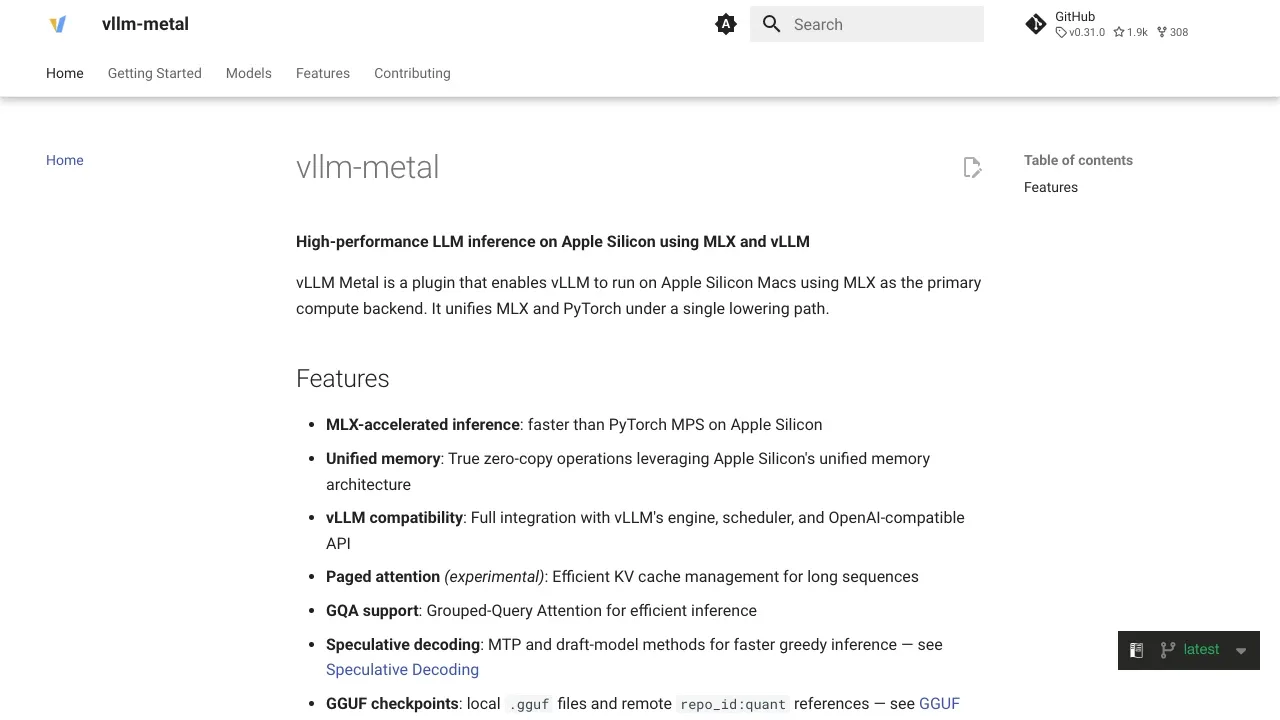
vLLM Metal lets developers serve language models on Apple Silicon Macs through vLLM. It's for people who want to use their Mac's hardware for local AI inference while keeping vLLM's API server and request scheduling.
- vLLM serving. Run models locally with vLLM's API server, scheduler, and paged memory management, using MLX as the primary compute backend.
- Qwen support. Supported models include
mlx-community/Qwen3.8-27B-8bit, which can run on a single Apple Silicon Mac. - Speculative decoding. The plugin supports speculative decoding for model inference.
- M5 acceleration. On M5 hardware, it uses NAX tensor units to accelerate prompt processing for supported attention types.
The community-maintained project is open source under the Apache 2.0 license. It requires an Apple Silicon Mac running macOS 15 (Sequoia) or later. Model computation runs on the Mac, and compatibility depends on the plugin's supported model set.
 Logotyper


