
vllm-mlx
Local LLM inference server for Apple Silicon Macs with OpenAI and Anthropic APIs, MLX GPU acceleration, and an Apache 2.0 license.
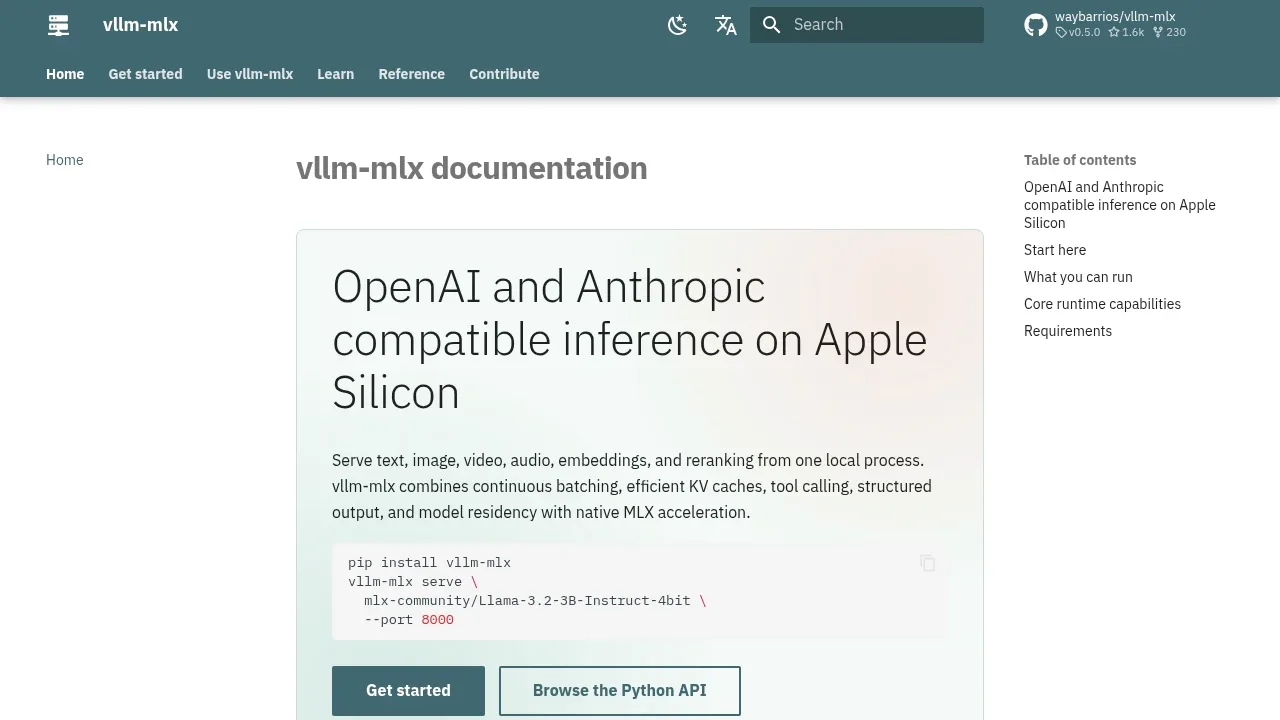
vllm-mlx is a local LLM inference server for developers who want to connect AI apps and coding assistants to models running on an Apple Silicon Mac. One process exposes both OpenAI-compatible and Anthropic-compatible APIs. It's open source under Apache 2.0 and runs on macOS with at least 8 GB of unified memory.
Native MLX acceleration uses Apple's Metal GPU backend without a model conversion step. Continuous batching handles concurrent requests, while a paged KV cache and shared prompt prefixes reduce repeated work and memory use. An optional SSD cache stores prefixes on disk for long-context agent sessions. The server can keep multiple models resident or load them dynamically.
Its capabilities extend beyond text generation:
- Image and video understanding with models such as Gemma 3, Qwen3-VL, Pixtral, and Llama vision.
- Speech recognition with Whisper and speech generation with Kokoro, Chatterbox, VibeVoice, and VoxCPM.
- Embeddings and query-document reranking for search applications.
- Tool calling through MCP, JSON Schema output constraints, and reasoning extraction for Qwen3 and DeepSeek-R1.
Model inference runs locally; the initial model download needs a connection. The API compatibility lets existing clients use the Mac as their model backend. Supported coding clients include Claude Code, OpenCode, Codex, and GitHub Copilot CLI. The server also exposes a Responses API and a Python API for applications that need direct access to generation.


