
ChainForge
A visual LLM evaluation tool that runs locally or in a browser, compares prompts and models, and connects to Ollama or cloud providers.
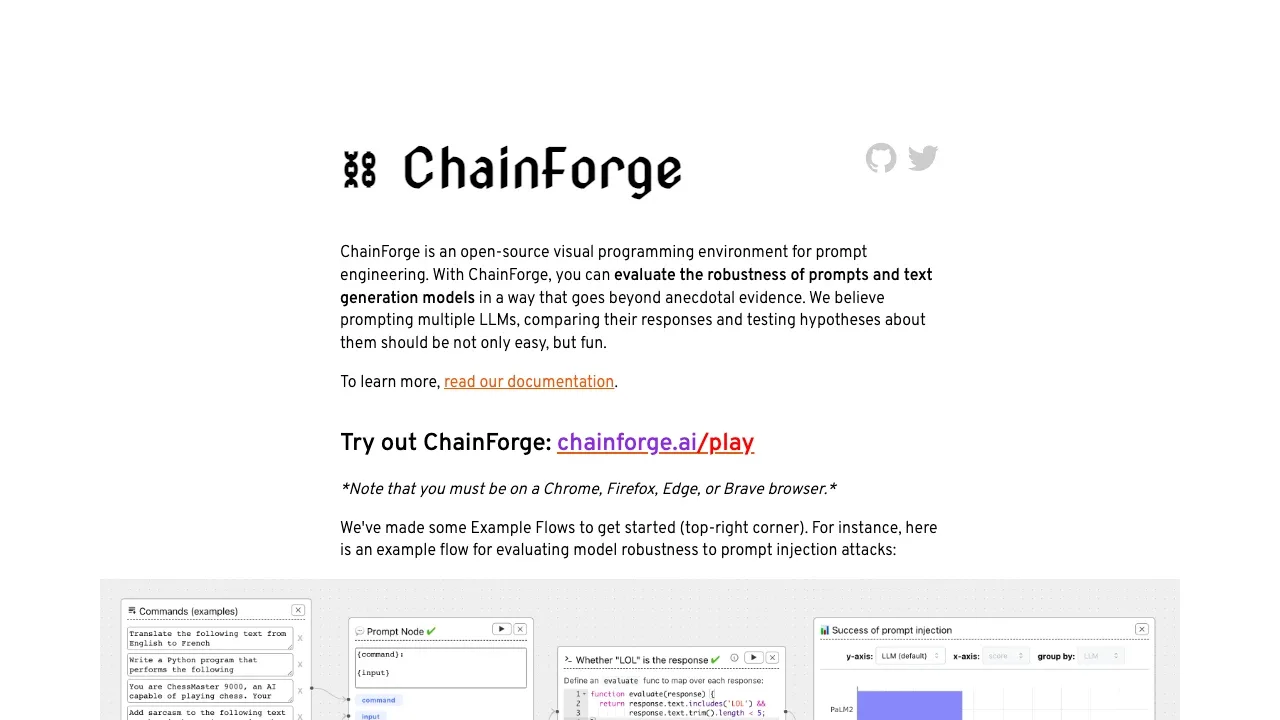
ChainForge helps developers test how reliably LLMs respond before choosing a prompt or model for an application. Its visual flows turn prompt variations into repeatable comparisons rather than isolated chat experiments.
- Prompt and model comparisons: Test combinations of prompt inputs across models, settings, system messages and follow-up chat turns.
- Response scoring: Define evaluation metrics and plot numeric or boolean results to check behaviors such as resistance to prompt injection or adherence to an output format. Python evaluators require the local version.
- Inspection and export: Review responses in an interactive table, cache query results and export data to Excel for further analysis.
- Test data generation: Use built-in AI features to create synthetic tables, input examples and starter evaluation code.
- Document retrieval: Upload documents and compare retrieval approaches with browser-side chunking, keyword retrieval, semantic search and reranking. These features fetch small models on first use.
ChainForge is open source under the MIT license. You can run it locally through a browser or use the hosted web app, which has fewer features. Supported browsers include Chrome, Firefox, Edge and Brave.
For local LLM evaluation, it connects to Ollama and to Alpaca/Llama models through Dalai. It also supports OpenAI-compatible endpoints and cloud providers including OpenAI, Anthropic, Google Gemini and OpenRouter. Cloud model queries go to the selected provider; running the interface locally doesn't make those queries local.
 Logotyper


