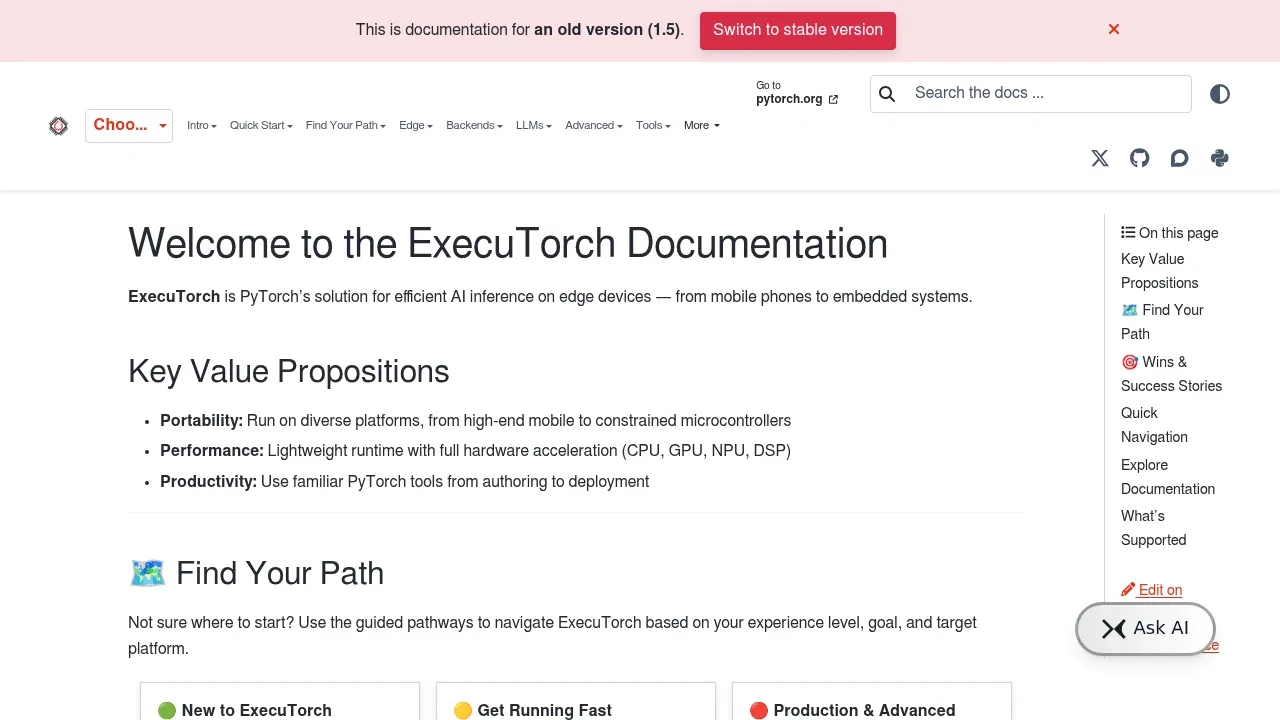
ExecuTorch is PyTorch's runtime for developers building AI into mobile apps, desktop software and embedded devices. It runs models on the user's hardware, with support for Android, iOS, Linux, macOS and Windows, as well as microcontrollers. Developers can reuse a PyTorch model across targets, though hardware-specific deployments need their own exported model files.
Its workloads include local LLM inference, computer vision and voice processing. Text models support quantization, long context, tool calling and speculative decoding. Voice capabilities include streaming and offline speech recognition, speech synthesis, voice activity detection and speaker diarization. Vision workloads cover image classification, object detection and segmentation, alongside multimodal models that work with text, images and audio.
The runtime can use CPU, GPU, NPU and DSP acceleration. Supported backends include XNNPACK for CPUs, Core ML for Apple platforms, OpenVINO on Linux and Qualcomm accelerators on Android. It delegates supported parts of a model to hardware backends and retains portable CPU kernels for fallback. Developers can keep the runtime small by including only the operators and hardware components their application needs.
Application APIs cover C++, Python, Swift/Objective-C and Kotlin/Java. Profiling and numeric debugging tools help developers inspect model performance and output, and the runtime supports custom operators and backends. ExecuTorch also runs AI features on Meta Quest and Ray-Ban Meta devices.
The README tracks the main branch. MLX, browser/WebGPU and the OpenAI-compatible local server are experimental paths; use release-matched documentation for deployment.
Claim this page with an email at pytorch.org. ExecuTorch gets the verified badge, and you can upgrade the listing to be featured on localhosted. Proud to be listed? Put our badge on your site.
Want more people to find ExecuTorch?Promote it
Something wrong or outdated on this page?
6.1KUpdated 5 days ago
macOS · iOS · Android#Hugging Face integration#Multimodal input#Quantization
Cactus is an on-device AI engine for developers building automation into mobile apps, wearables and embedded devices. Its Needle model handles tool calling locally, so a device can turn a request into an action without an internet connection. The focus is small devices, including smart home hardware, robots and microcontrollers.
3.5KUpdated 19 hours agoApache-2.0
macOS · Windows · Linux · iOS · Android · Web#Agent Skills#Hugging Face integration#Multimodal input
16.2KUpdated 1 day agoApache-2.0
Windows · iOS · Android#Image-to-image#Multimodal input#ONNX
23.9KUpdated 6 days ago
macOS · Windows · Linux · iOS · Android · Web#ONNX#Quantization
ncnn is a C++ framework for developers building on-device AI into mobile, desktop and embedded applications. Its focus is running neural networks with a small memory footprint and no third-party runtime dependencies. Models run on the target device's CPU or a supported Vulkan GPU.
10.9KUpdated 23 hours agoApache-2.0
macOS · Windows · Linux#Hugging Face integration#Multimodal input#ONNX
1.7KUpdated 2 days ago
Linux#Multimodal input#Quantization
RKLLM is a software stack for developers building local AI applications on Rockchip hardware. It uses the chip's neural processing unit (NPU) to run language and multimodal models on development boards, with support for the RK3588, RK3576, RK3562 and RV1126B series.
LiteRT is Google's open-source framework for developers building AI into apps that run on users' own devices. It succeeds TensorFlow Lite and covers model conversion, optimization and local inference. It's licensed under Apache 2.0.
MNN is a lightweight C++ framework for developers who want AI models to run on phones, PCs and embedded devices. It handles inference and training on the device, with a focus on small application footprints and hardware acceleration. The project is open source under Apache 2.0, and Alibaba uses it in apps including Taobao, Youku and DingTalk.
OpenVINO is an Apache 2.0 licensed toolkit for developers who want to run AI models locally or serve them on their own infrastructure. It converts and optimizes models for inference, with support for x86 and ARM CPUs, Intel integrated and discrete GPUs, and Intel NPUs. Its runtime works on Linux, Windows and macOS.