
FastEmbed
A Python library that generates local embeddings and reranks search results, with CPU or GPU support and Qdrant integration.
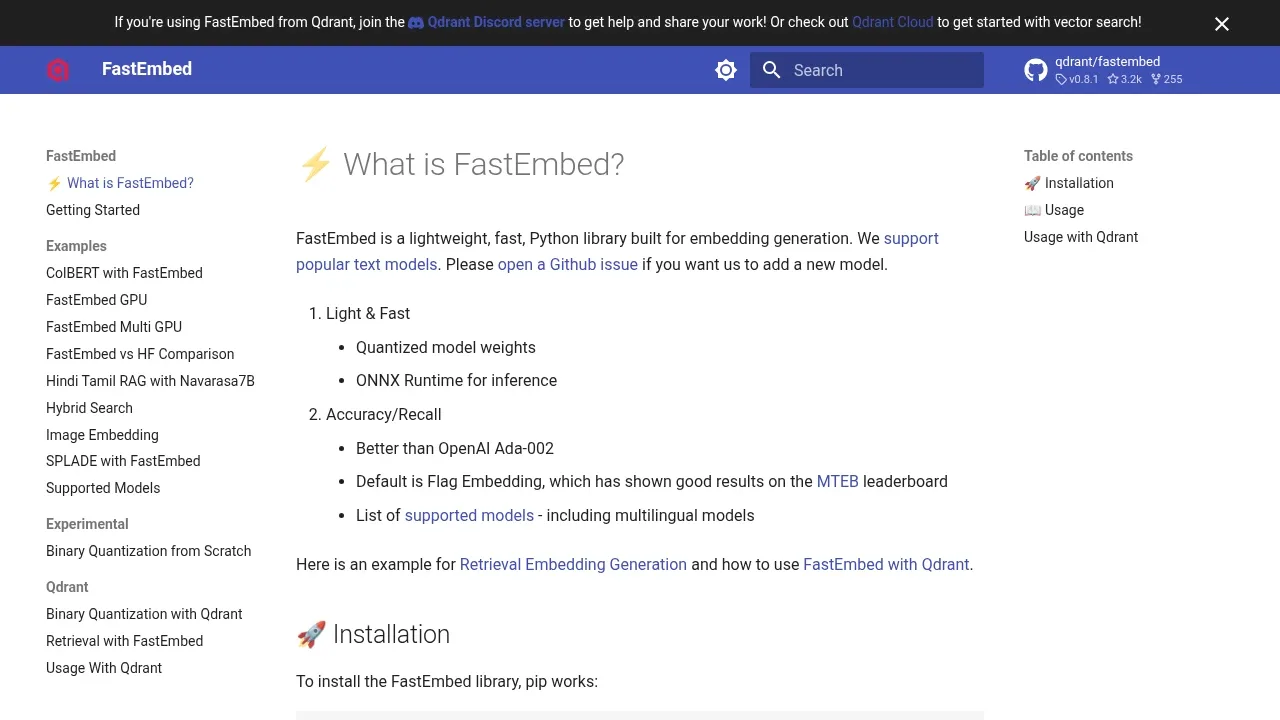
FastEmbed is a Python library for developers building semantic search and retrieval-augmented generation (RAG). It turns text into vectors and evaluates search results on your own hardware without requiring a cloud embedding API.
- Dense text embeddings: Encode documents and queries with Flag Embedding as the default, with multilingual models and support for adding custom dense embedding models.
- Sparse text embeddings: Generate sparse text representations with SPLADE++ for retrieval systems.
- Search reranking: Use text cross encoders to reorder search results, including models beyond the supplied selection.
- Qdrant integration: Embed documents and search by text through the Qdrant Python client, including with an in-process database.
FastEmbed uses ONNX Runtime and quantized model weights, with few external dependencies and no PyTorch requirement. It runs on a CPU or uses GPU acceleration with CUDA support. Parallel encoding supports processing large datasets.
Qdrant maintains the library, which is open source under Apache 2.0. It can also run in serverless environments such as AWS Lambda; in that deployment, processing takes place in the cloud.
 Logotyper


