Folio OCR
A local OCR workbench turns PDFs and images into editable documents using GLM-OCR through Ollama, with Word, Markdown and EPUB export.
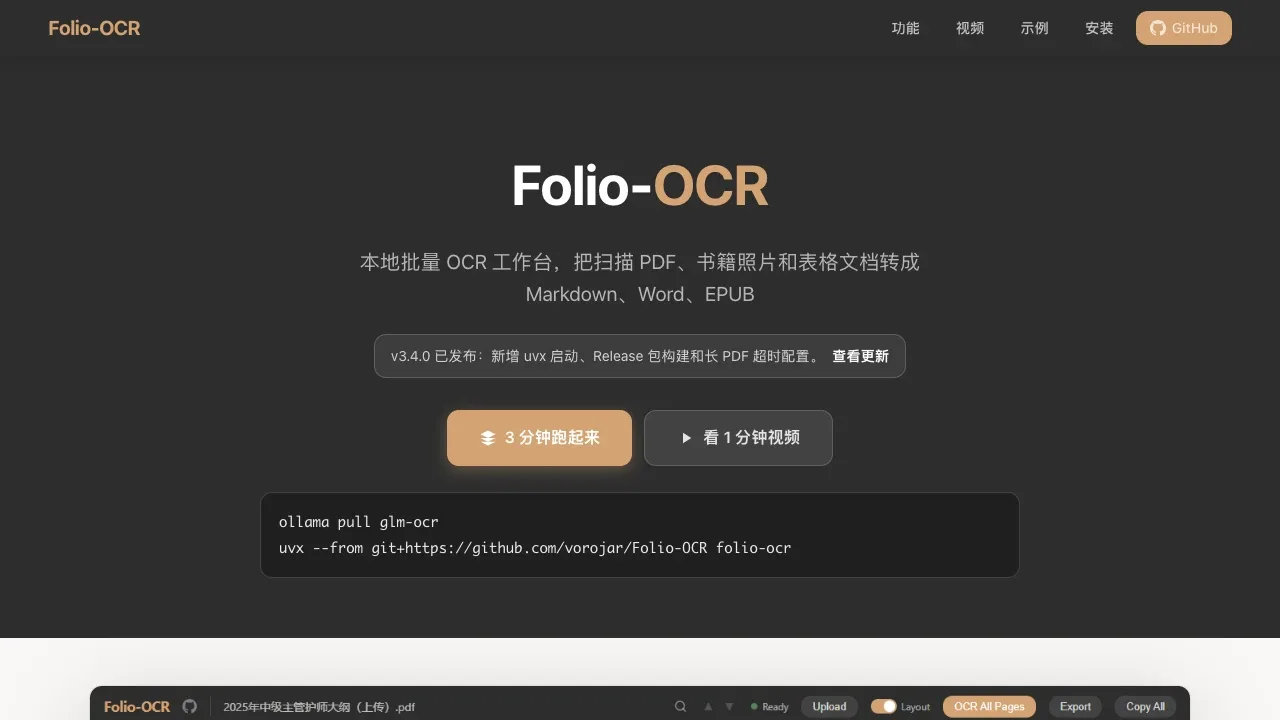
Folio OCR is a local AI workbench for turning scanned PDFs, book photos and document images into editable text. It's aimed at book digitization and batch transcription where headings, paragraphs and tables need to survive recognition.
- Batch recognition: Process PDFs and PNG, JPG, GIF or BMP images together, with progress estimates and the ability to stop recognition.
- Page structure: PP-DocLayoutV3 identifies headings, body text, tables and images before GLM-OCR reads the page through Ollama.
- Proofreading: Compare page images with recognized text in a three-panel editor, use linked region highlights, search across pages and merge paragraphs broken by line wraps.
- Document export: Save Markdown, plain text, Word documents or EPUB ebooks, with Markdown and HTML table previews available while editing.
- Saved work: Automatic local saves preserve documents, recognition results and edits across restarts, and the interface restores the last open document.
The browser interface connects to a locally running service, which can also run through Docker Compose. OCR works offline with the required models available locally; documents don't need to go to a third-party OCR service. NVIDIA GPU acceleration is supported, while layout analysis uses the CPU by default. Folio OCR is free and open source under the MIT license.
 Logotyper


