
GPT Crawler
A local web crawler turns website text into JSON knowledge files for OpenAI custom GPTs and assistants, with Docker and self-hosted API support.
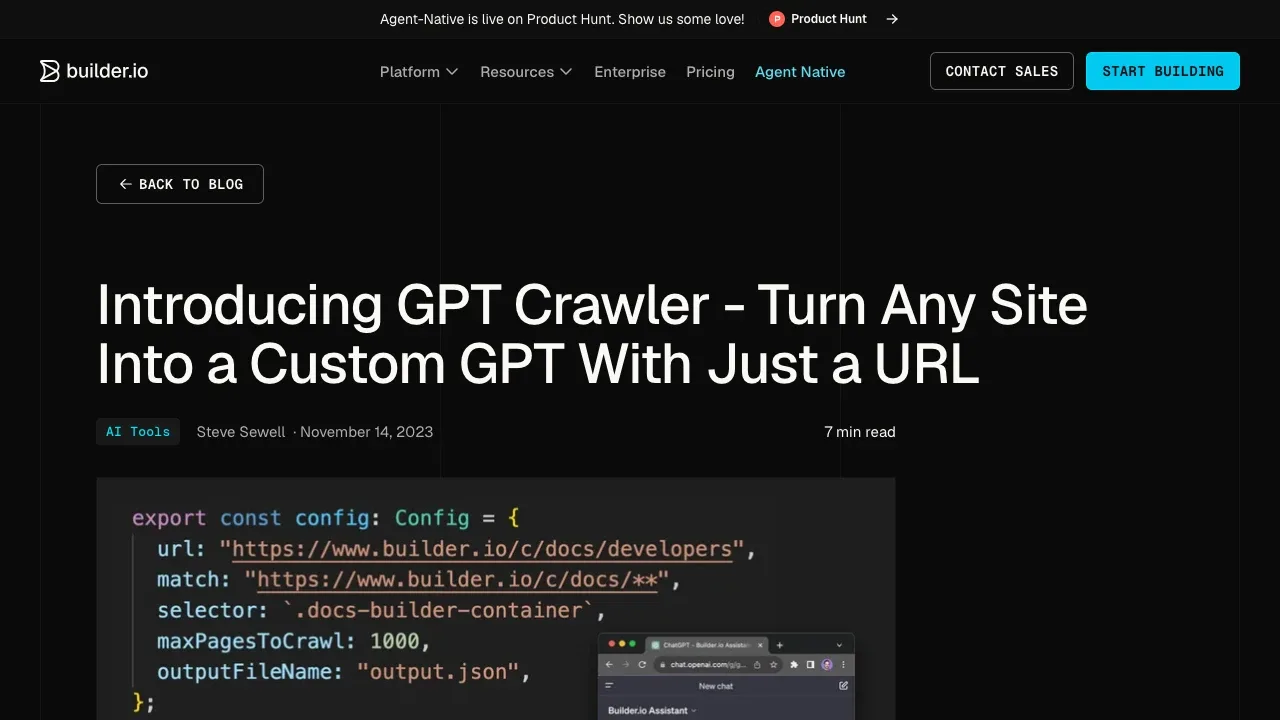
GPT Crawler collects website text into knowledge files for people building AI assistants around documentation or other web content. It prepares the material a custom GPT or assistant can use to answer questions about a site.
- Website collection: Crawl one or multiple URLs, or use a sitemap to collect pages across a site.
- Focused text extraction: Choose which parts of a page to capture and restrict the crawl to matching links so the output contains the content you need.
- Knowledge file export: Generate JSON files for upload to OpenAI, with file size and token limits to keep the output manageable.
- API access: Run the crawler as a self-hosted API so other applications can request crawls.
The crawler is free and open source under the ISC license. It runs locally with Node.js or in Docker, and writes the collected content to local files. Crawling online websites needs an internet connection.
The OpenAI workflow is separate from the local crawler: you upload the generated files to OpenAI to use them in a custom GPT or assistant. That sends the collected content to OpenAI, where the assistant runs.
 Logotyper


