
llm-fw
A local LLM firewall blocks suspected prompt injection and redacts secrets on Windows, macOS and Linux, with CPU-based inspection and no telemetry.
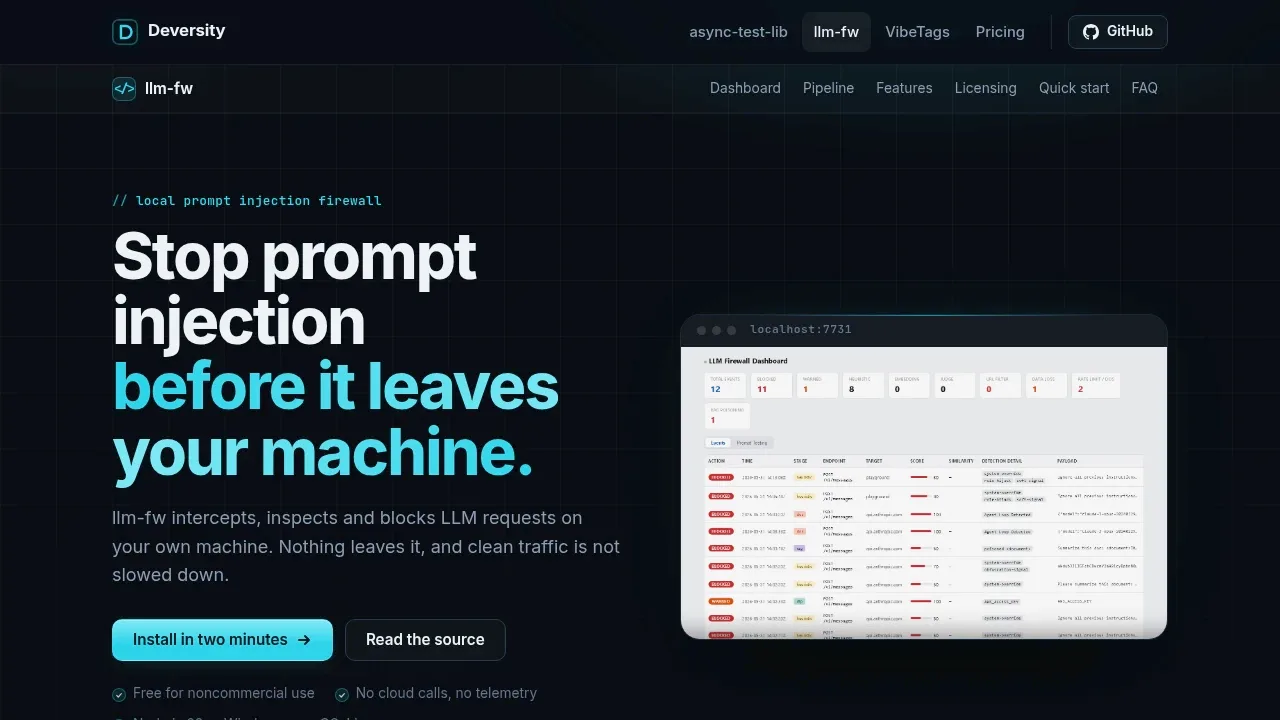
llm-fw inspects model requests for developers and teams using AI tools, SDKs and agents. It blocks suspected prompt injection and removes outgoing secrets before forwarding approved traffic to the model endpoint.
- Prompt injection checks. Local detection examines encoded text and multilingual attacks, with an optional Ollama judge using qwen2.5:3b or an ONNX classifier for ambiguous prompts.
- Secret redaction. Outbound scanning removes matching credentials, private keys, payment card numbers and US social security numbers from requests.
- Untrusted content checks. Retrieved documents and tool results can use stricter detection thresholds than user prompts, with checks for invisible Unicode and text in pasted screenshots.
- Agent loop limits. Request and token rate limits, plus a circuit breaker for repeated payloads, can interrupt agents caught in costly loops.
- Local review dashboard. You can inspect detection scores and decoded payloads, test prompts, and mark false positives to reduce repeat blocks.
It runs on Windows, macOS and Linux, or as a shared team proxy. Detection uses your CPU, requires no account and makes no cloud calls of its own; logs stay on local disk. Approved requests still reach your chosen provider. Supported services include OpenAI, Anthropic, Gemini, Vertex AI and AWS Bedrock, plus OpenAI-compatible self-hosted endpoints such as vLLM, LM Studio and LocalAI.
The PolyForm Noncommercial License permits free noncommercial use. Commercial use requires a separate licence, and embedding it in a product for sale requires an OEM agreement.


