
LLM Router
A self-hosted AI gateway connects Ollama, vLLM, llama.cpp, LM Studio and cloud APIs, with optional PII masking, routing and provider failover.
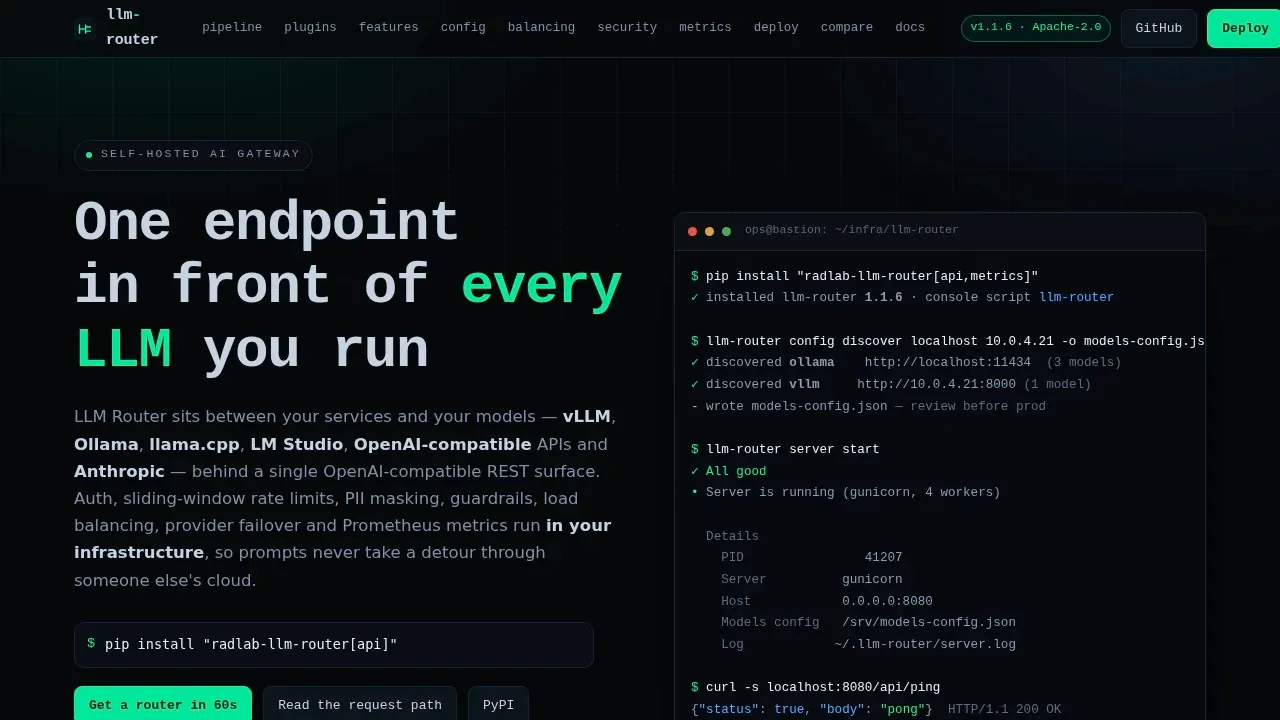
LLM Router is a self-hosted AI gateway for teams connecting applications to local LLM servers and cloud providers. It puts a shared interface in front of your models so clients can use the same gateway across backends.
- Compatible model access: Connect vLLM, Ollama, llama.cpp, LM Studio, OpenAI-compatible APIs and Anthropic, with chat, Responses, embeddings and native Anthropic messages support, including streaming.
- Privacy and safety checks: Optional plugins mask personal information or block prompts before they reach a model; local regex masking covers email, phone and Polish identifiers, while ML detection in Polish and English and model-based safety checks use separate HTTP services.
- Model selection and failover: Select models by intent, task complexity or embedding similarity, distribute requests across providers, and use standby providers or fallback models when the primary providers are unavailable.
- Coding agents and document context: Plugins route Codex CLI work by task type, map Claude Code model names to local or custom models, and add relevant document passages through LangChain retrieval.
- Access and monitoring: Scoped API keys and Redis rate limits control client access, while Prometheus metrics and a supplied Grafana dashboard track latency, errors, retries and token usage.
The gateway is open source under Apache 2.0 and runs in your own infrastructure, including containers, on premises or in the cloud. It sends no telemetry and needs no external control plane. Requests to local providers can remain within your network; selecting OpenAI or Anthropic sends them to those services. HTTP-based masking and guardrail plugins also send text to their configured services. Authentication, masking, guardrails and other optional controls are off until enabled.


