
OpenRLHF
An open-source RLHF framework trains HuggingFace models on your own GPUs, with distributed training and support for multi-turn agents.
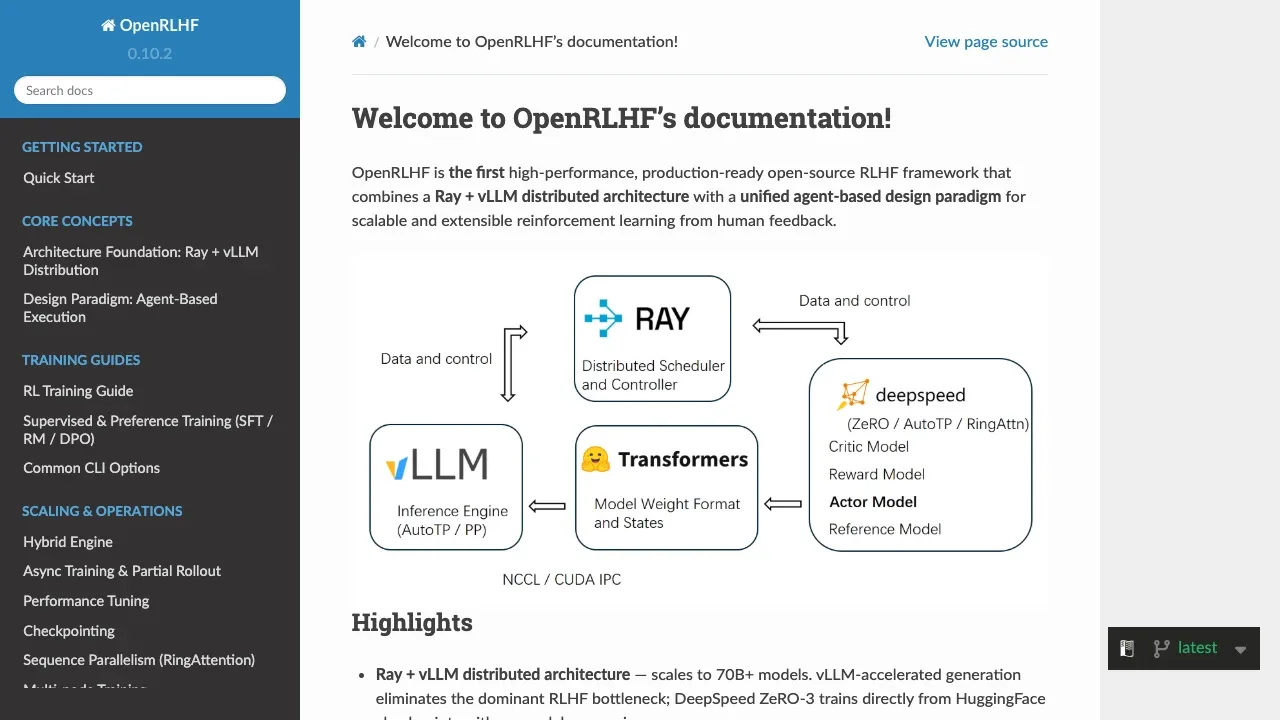
OpenRLHF is a self-hosted Python framework for researchers and teams training language models with human feedback or custom rewards. It supports fine-tuning and reinforcement learning on your own GPU hardware, including training agents that interact with an environment.
- Training and preference learning: Train reward models, run supervised fine-tuning, or use DPO, IPO and cDPO to learn from preference data. Reinforcement learning methods include PPO, REINFORCE++, GRPO and RLOO.
- Agent training: Train on single responses or multi-turn interactions with environment feedback and custom rewards. An asynchronous pipeline supports multi-turn workloads, and a local OpenAI-compatible vLLM server can collect training traces for external tool-use frameworks.
- Model support: Work directly with HuggingFace Transformers models, including vision-language models that receive image feedback. LoRA, QLoRA and mixture-of-experts models are supported.
- Distributed GPU use: Ray distributes work, vLLM generates responses, and DeepSpeed handles training. Training models and generation engines can share GPUs, while multi-node training supports workloads spread across servers with SLURM.
OpenRLHF is open source under Apache 2.0 and uses a CUDA GPU stack. It also offers Molt, an Automodel-powered training backend. TensorBoard and Weights & Biases integrations provide training logs; checkpoint recovery lets interrupted runs resume, and evaluation metrics can determine which checkpoint to save.
 Logotyper


