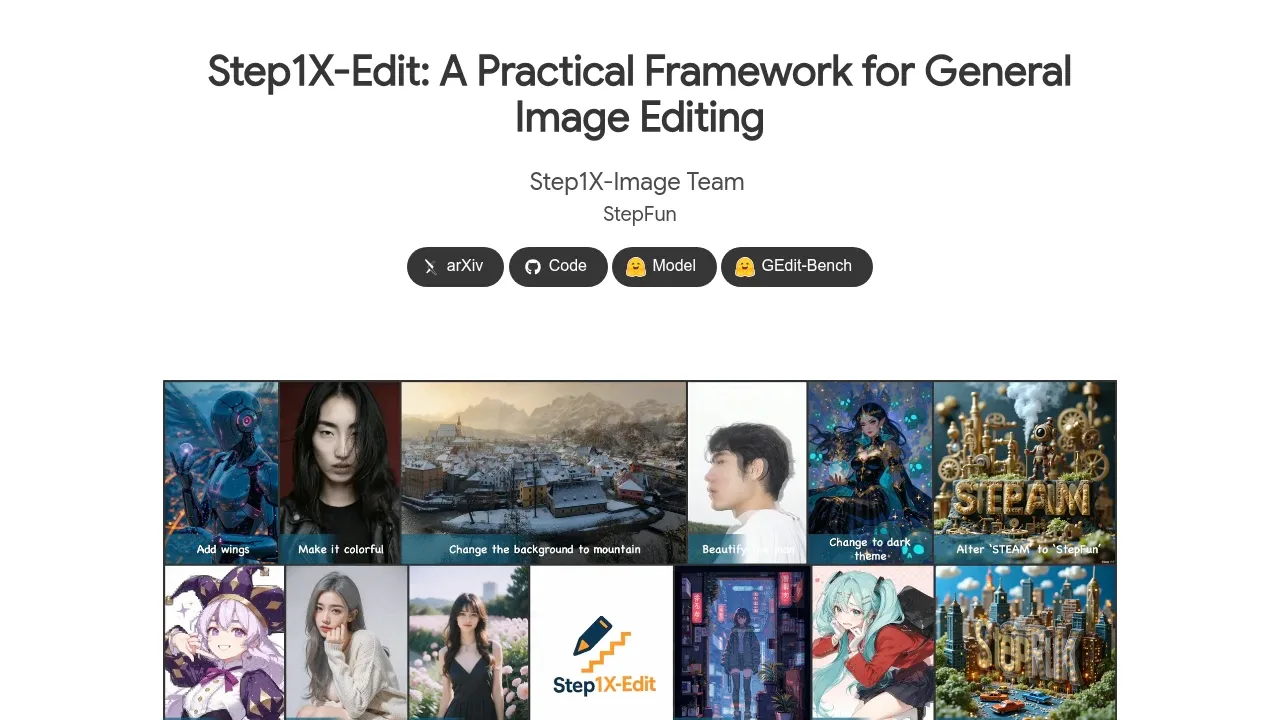
Step1X Edit is an open-source image editing model for developers and researchers who want to edit existing pictures with written instructions on their own GPU hardware. It handles changes to individual objects as well as the overall appearance of an image. The code uses the Apache 2.0 license.
Its editing range includes adding or removing subjects, replacing objects, changing backgrounds and adjusting colors or materials. It can also alter facial expressions and poses, retouch portraits, and change or remove text within an image. Style edits include pixel art, clay-like surfaces and oil painting effects, so the same model covers both targeted corrections and broader visual changes.
The model combines a multimodal language model, which processes the reference image and editing request, with a diffusion decoder that produces the edited picture. It works with Hugging Face Diffusers. For people comparing image editing models, the accompanying GEdit-Bench evaluates tasks drawn from real user requests and includes English and Chinese evaluations.
Local inference uses a CUDA-based GPU setup, and the published performance tests use NVIDIA H800 GPUs. The project provides ways to reduce GPU memory use, distribute inference across multiple GPUs with xDiT, and accelerate it with TeaCache. Developers can fine-tune the model with LoRA and use those weights for specialized edits; an included LoRA targets damaged hands in anime images.
Claim this page and we'll verify you by hand. Step1X Edit gets the verified badge, and you can upgrade the listing to be featured on localhosted. Proud to be listed? Put our badge on your site.
Want more people to find Step1X Edit?Promote it
Something wrong or outdated on this page?
4.3KUpdated 10 months agoMIT
Web#Hugging Face integration#Image-to-image#LoRA
OmniGen is a local AI image generation model that handles text prompts, reference images, and image editing within one model. It's for creators who want to reuse subjects across images and developers building image tools on their own hardware. The code is open source under the MIT license.
1.7KUpdated 2 years ago
Web#Image-to-image#Inpainting#Multimodal input
BrushNet adds text-guided image inpainting to pretrained diffusion models, letting you fill selected areas of an image while retaining the surrounding content. It's for developers and researchers who want to run image editing on their own hardware and work with an existing model's visual style.
4.6KUpdated 2 years agoApache-2.0
Web#ControlNet#Hugging Face integration#Image-to-image
4.3KUpdated 10 months ago
Linux · Web#ControlNet#Hugging Face integration#Image-to-image
HunyuanDiT is a text-to-image diffusion transformer for people who want to generate images on their own hardware using Chinese or English prompts. Its focus on Chinese language and cultural references makes it relevant for scenes drawn from poetry, idioms, food and architecture. It also handles long descriptions with details about subjects, clothing, lighting and artistic style.
576Updated 1 day agoGPL-3.0
macOS · Linux · iOS · Docker#Image-to-image#Inpainting#LoRA
165.2KUpdated 2 years agoAGPL-3.0
macOS · Windows · Linux · Web#Batch processing#Code execution#Image-to-image
Kolors is a text-to-image model for people who want to generate photorealistic images on their own hardware, including work with Chinese prompts and Chinese cultural content. Developed by Kuaishou, it understands prompts in Chinese and English and can render text in both languages within generated images.
Draw Things is an AI image generation app for iPhone, iPad and Mac that keeps generation on your device and works offline. It's for people who want to create and edit images without sending that work to a cloud service, including artists developing character concepts or trying out apparel designs.
Stable Diffusion web UI (AUTOMATIC1111) is a browser interface for generating and editing images with models running on your own hardware. It's for artists and anyone who wants control over prompts, models and image variations. The software is open source under AGPL-3.0.