
VibeVoice
An open-source voice AI model family for local transcription and speech generation, with CPU recognition and streaming text-to-speech under the MIT license.
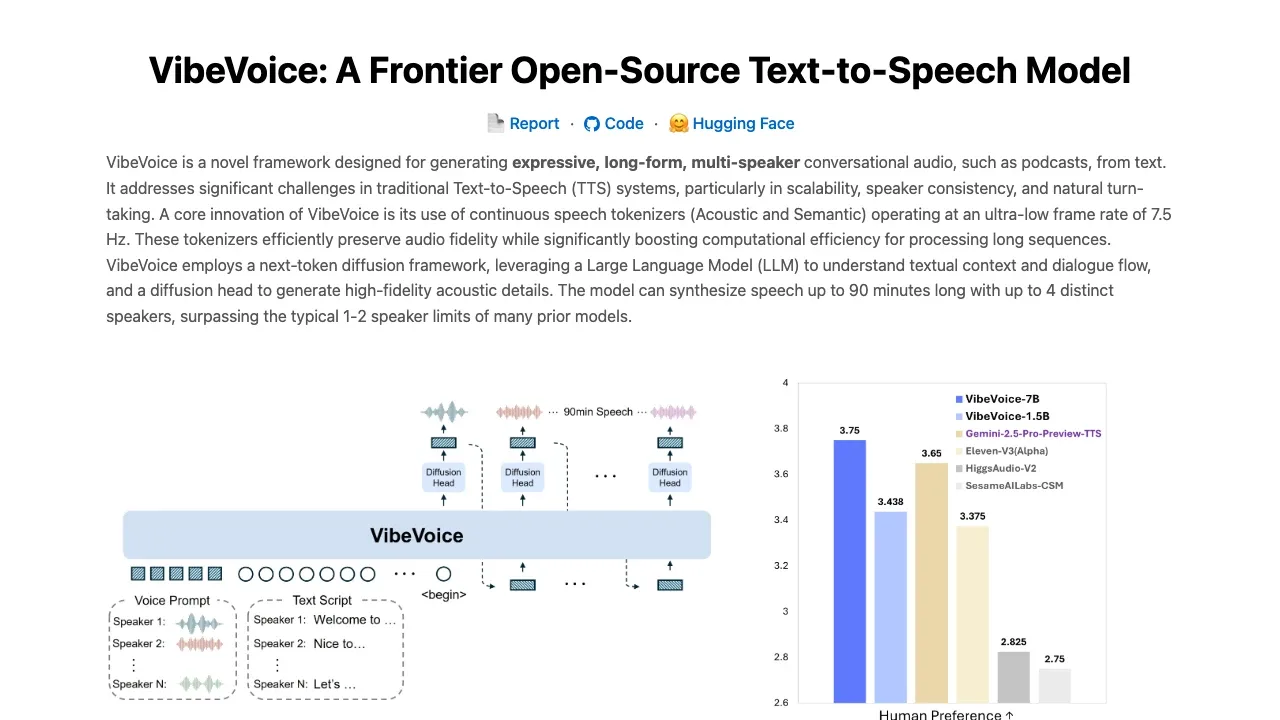
VibeVoice is a family of voice AI models for developers and researchers building transcription and speech generation applications. It can capture who spoke and when, or produce spoken responses from incoming text.
- Long-recording transcription: VibeVoice-ASR processes up to an hour of audio in one pass and returns text with speaker labels and timestamps.
- Streaming recognition: VibeVoice-ASR-Streaming transcribes speech as it arrives, with speaker tracking, multilingual support and custom hotwords.
- Vocabulary guidance: Custom hotwords let you supply names, technical terms or background context to guide speech recognition.
- CPU recognition: VibeVoice-ASR-BitNet runs locally without a GPU, with real-time inference on three or more CPU threads.
- Streaming speech generation: VibeVoice-Realtime accepts text incrementally and generates speech before the full input is available, with support for extended spoken output.
The project is open source under the MIT license. VibeVoice-ASR works with Hugging Face Transformers. The CPU inference engine runs on your hardware; Microsoft Foundry and online playgrounds provide hosted ways to try speech recognition.
Transcripts and generated speech can contain errors or reflect model biases. The project recommends further testing and development before commercial or real-world use. Quick-try access for the original VibeVoice-TTS model is disabled; VibeVoice-Realtime remains available for speech generation.
 Logotyper


