
LiteLLM
A self-hosted AI gateway and Python SDK connects cloud and local models through an OpenAI-compatible API, with spend controls and request routing.
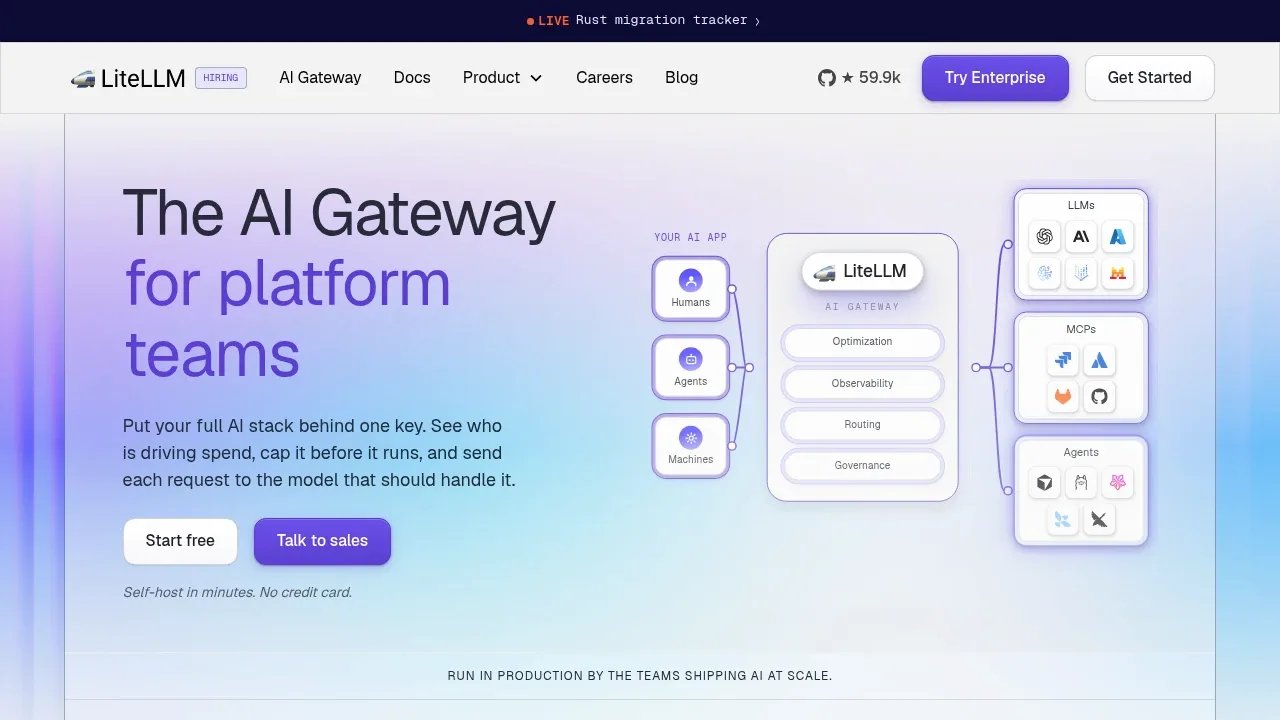
LiteLLM is an AI gateway for platform teams managing model access across applications and providers. It puts cloud and self-hosted models behind a shared interface so developers can switch providers without rewriting their integration.
- Model access: Connect OpenAI, Anthropic, Gemini, Bedrock and Azure alongside self-hosted backends such as vLLM and NVIDIA NIM through an OpenAI-compatible API or Python SDK.
- Usage controls: Issue virtual keys, restrict model access, track spending by user or team, and enforce budgets and rate limits that stop requests at the cap.
- Routing and caching: Balance requests across deployments, route to lower-cost models and reuse cached responses.
- Request oversight: Inspect model activity and request logs, and apply guardrails to model calls.
- Tools and other AI requests: Handle embeddings, images and audio, and access A2A agents and MCP servers through the gateway.
The gateway can run on your own infrastructure with Docker or Kubernetes, including air-gapped environments when connected models and services are available there. Requests routed to cloud models still go to those providers. A hosted proxy is also available.
LiteLLM runs on macOS, Linux and Windows. Some features use the LiteLLM Commercial License.
 Logotyper


