
LLM Compressor
An open-source Python library compresses local or Hugging Face models for vLLM, with weight and KV cache quantization under Apache 2.0.
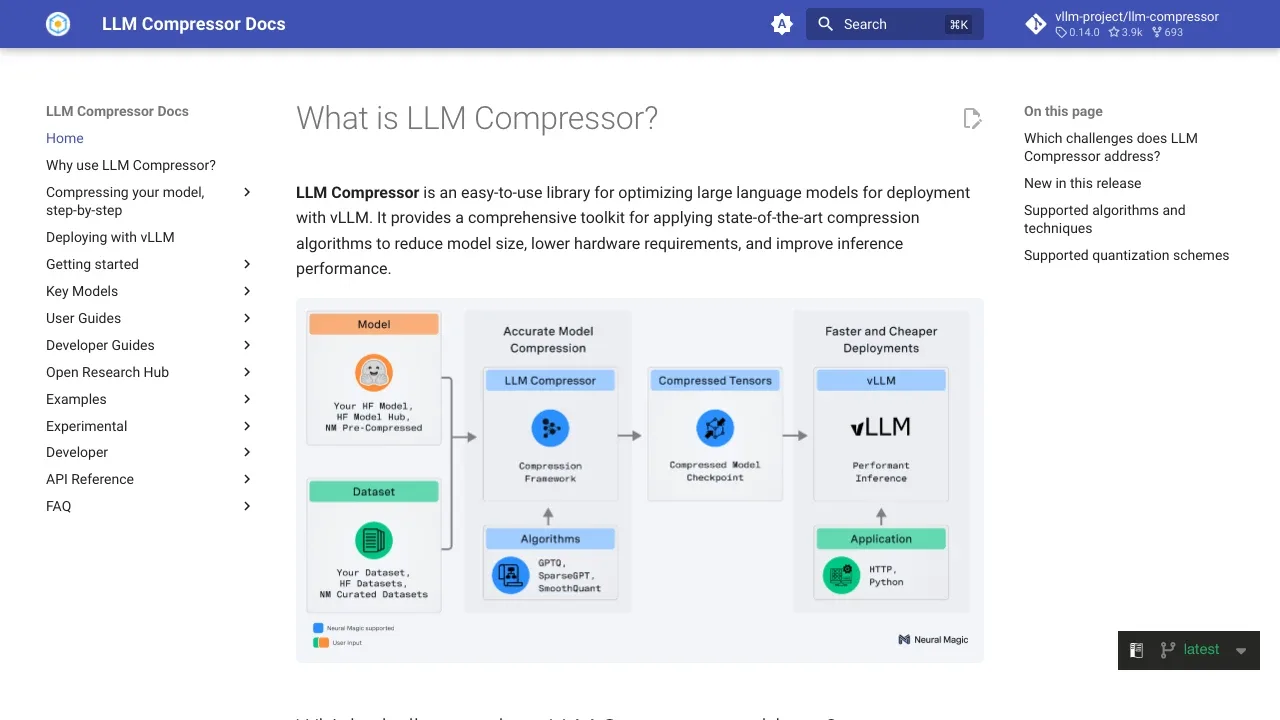
LLM Compressor prepares models for deployment with vLLM by reducing their storage and memory requirements through quantization. It's for developers working with local checkpoints or models from Hugging Face repositories.
- Model quantization: Compress weights, activations, attention and the KV cache, which holds information used during text generation, with formats including INT4, INT8, FP8, NVFP4 and MXFP4.
- Compression methods: Choose GPTQ, AWQ or AutoRound for weight quantization, and apply different precision settings to different parts of a model.
- Multimodal models: Quantize mixture-of-experts LLMs, vision-language models and audio-language models.
- vLLM-compatible output: Save compressed checkpoints in compressed-tensors format for inference with vLLM.
Compression runs separately from model serving. For large models, the library supports disk offloading and distributed data parallel quantization with GPTQ across GPUs.
LLM Compressor is an open-source Python library licensed under Apache 2.0. It accepts local or remote Hugging Face-compatible checkpoints, including Qwen3-30B-A3B.
 Logotyper


