
LLMLingua
An open-source Python library compresses LLM prompts and KV caches, with long-context methods and integrations for LangChain and LlamaIndex.
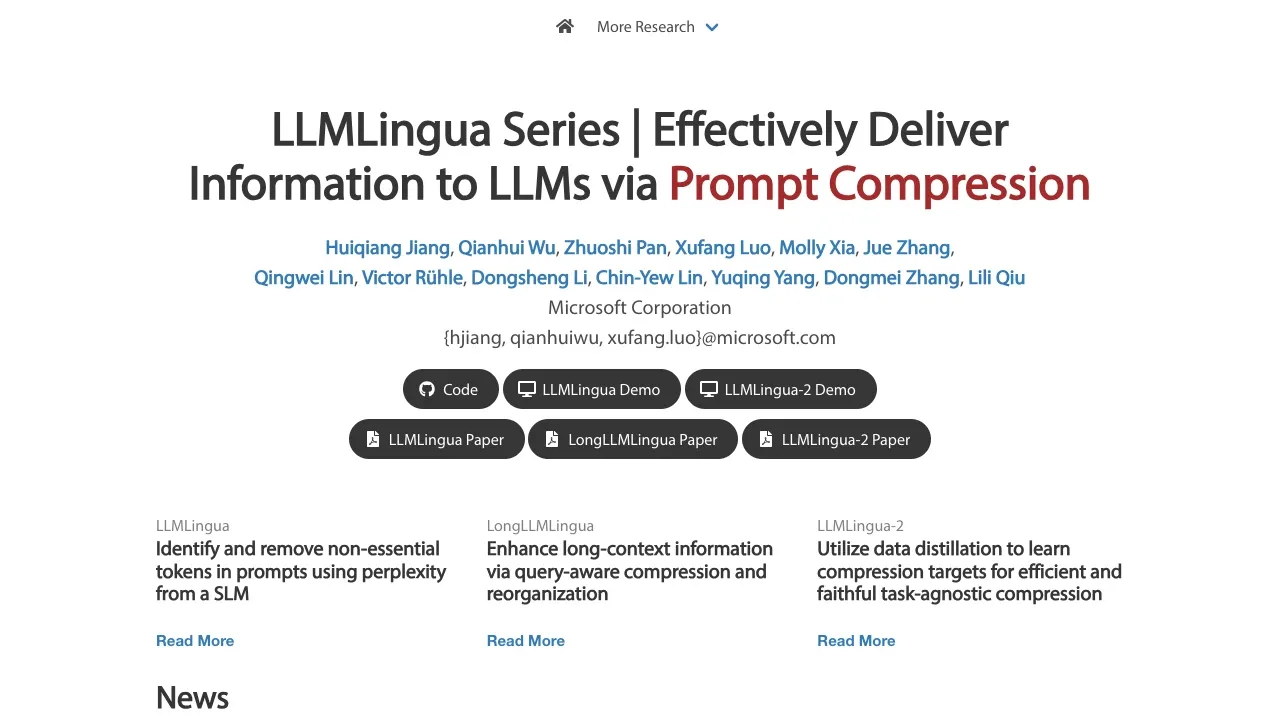
LLMLingua is a Python library for developers building LLM applications that need to fit lengthy input into a model's context window or reduce token costs. It uses smaller models to remove less useful text before the prompt reaches the answering model.
- Prompt compression: Shorten retrieved documents, meeting transcripts, code and reasoning examples without retraining the LLM that answers them.
- Long-context retrieval: LongLLMLingua prioritizes information relevant to a question and addresses the tendency of models to overlook material in the middle of long inputs.
- Selective preservation: Keep chosen sections or tokens intact while applying different compression rates to the rest of a prompt.
- Compression models: LLMLingua-2 provides task-independent compression, while SecurityLingua compresses suspicious prompts to expose malicious intent for jailbreak detection.
- KV-cache compression: Reduce the model's stored attention context to accelerate inference.
The library is open source under the MIT license and runs compression models in your own Python environment. Supported choices include GPT2-small, LLaMA-7B, Phi-2 and GPTQ-quantized Llama-2 models. The supplied quantized Llama-2 example uses less than 8 GB of GPU memory.
LLMLingua integrates with LangChain, LlamaIndex and Prompt flow. Local compression is separate from the answering model: using a cloud LLM still sends the compressed prompt to that service.
 Logotyper



