
RWKV
An open-source LLM architecture with constant-memory inference and parallel training, plus Python and PyTorch code under Apache 2.0.
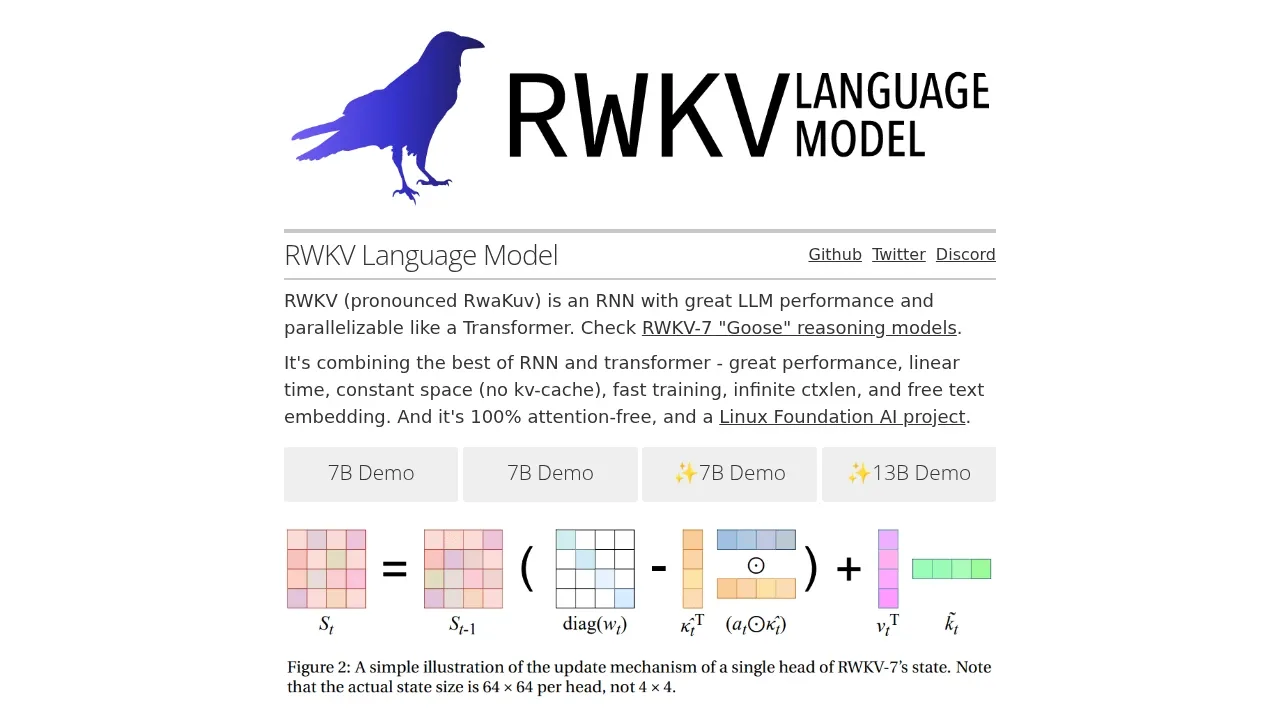
RWKV is a language model architecture for developers and researchers building LLM applications or training models. Its recurrent design keeps inference memory constant as text grows, making it relevant when a growing context cache would strain available memory.
- Long-sequence processing: RWKV processes sequences in linear time without a key-value cache or a fixed architectural context-length limit.
- Training and fine-tuning: Python and PyTorch code supports training your own models and adapting existing checkpoints, with parallel training similar to GPT-style models.
- State tuning: You can adapt a model's initial recurrent state without adding inference overhead, though the supplied tuning implementation uses as much VRAM as full supervised fine-tuning.
- Multimodal development: Related projects such as Vision-RWKV and Diffusion-RWKV apply the architecture to image tasks alongside its language applications.
RWKV is free and open source under Apache 2.0. The main training stack uses CUDA and DeepSpeed. The separate nanoRWKV project supports CPU or GPU training without a custom CUDA kernel. RWKV provides a model architecture and development code rather than a packaged chat interface.


