
VoxCPM
An open-source text-to-speech system generates multilingual audio locally, with voices designed from descriptions or cloned from recordings.
Alternative to:
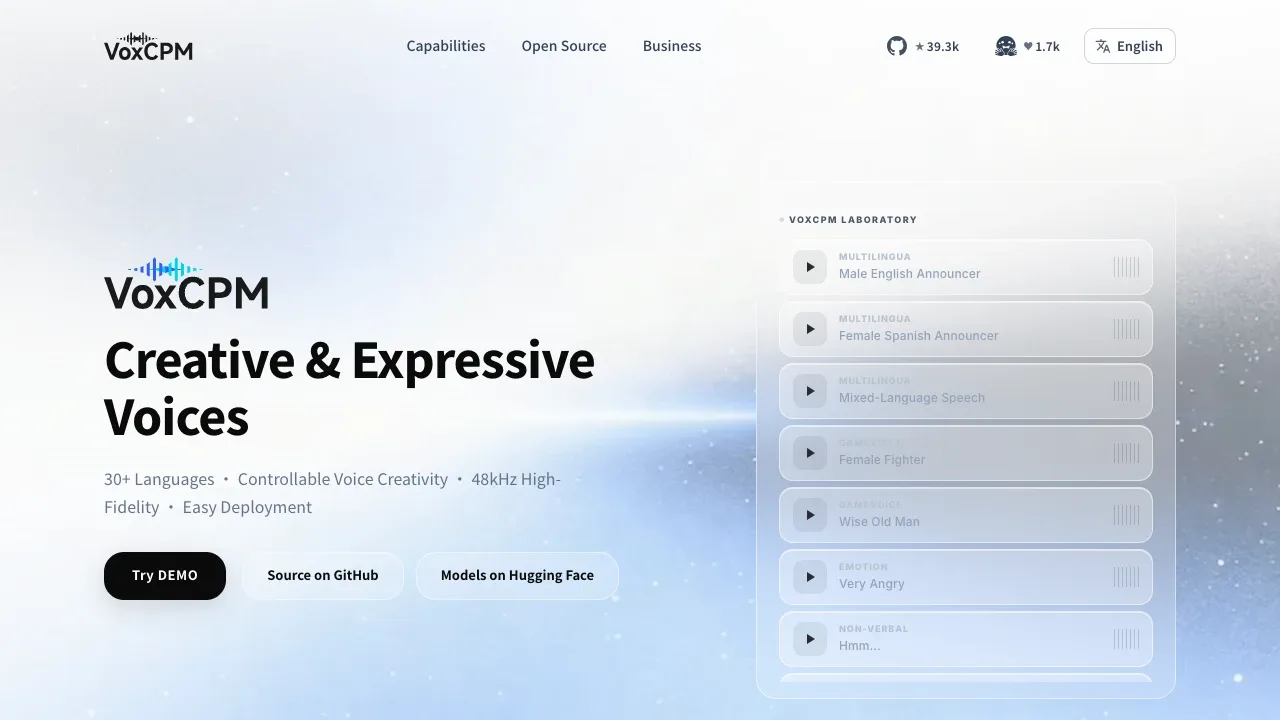
VoxCPM is a local text-to-speech system for developers and audio creators who want to generate speech with voices they can design or clone. It supports multilingual narration and control over how a voice delivers the text.
- Voice design: Describe a voice's age, tone, emotion or pace in plain language to create speech without a reference recording.
- Voice cloning: Use a short recording to reproduce a speaker's timbre and adjust the delivery, or add its transcript to guide rhythm, emotion and style more closely.
- Multilingual speech: Generate speech in languages including English, Chinese, Arabic, Spanish and Japanese, with support for Chinese dialects and delivery inferred from the text's meaning.
- Streaming and integration: Receive audio as it's generated, with Nano-vLLM-VoxCPM and vLLM-Omni supporting concurrent requests for self-hosted services; vLLM-Omni also provides an OpenAI-compatible speech API.
- Model adaptation: Fine-tune the model with full training or LoRA to adapt it to your speech data.
You can run it locally through a Python API, command-line tool or browser interface. It supports CPU, NVIDIA CUDA and Apple Silicon acceleration. The VoxCPM2 model uses roughly 8 GB of VRAM and produces 48 kHz audio. For on-device use without Python, llama.cpp-omni supports GGUF weights with CPU, Metal, CUDA and Vulkan backends, including macOS and Linux deployment.
The code and model weights use the Apache 2.0 license and are free for commercial use.
 Logotyper


