
Voxtral
An open-source audio AI model for offline transcription, translation and recording Q&A, with vLLM and Transformers support under Apache 2.0.
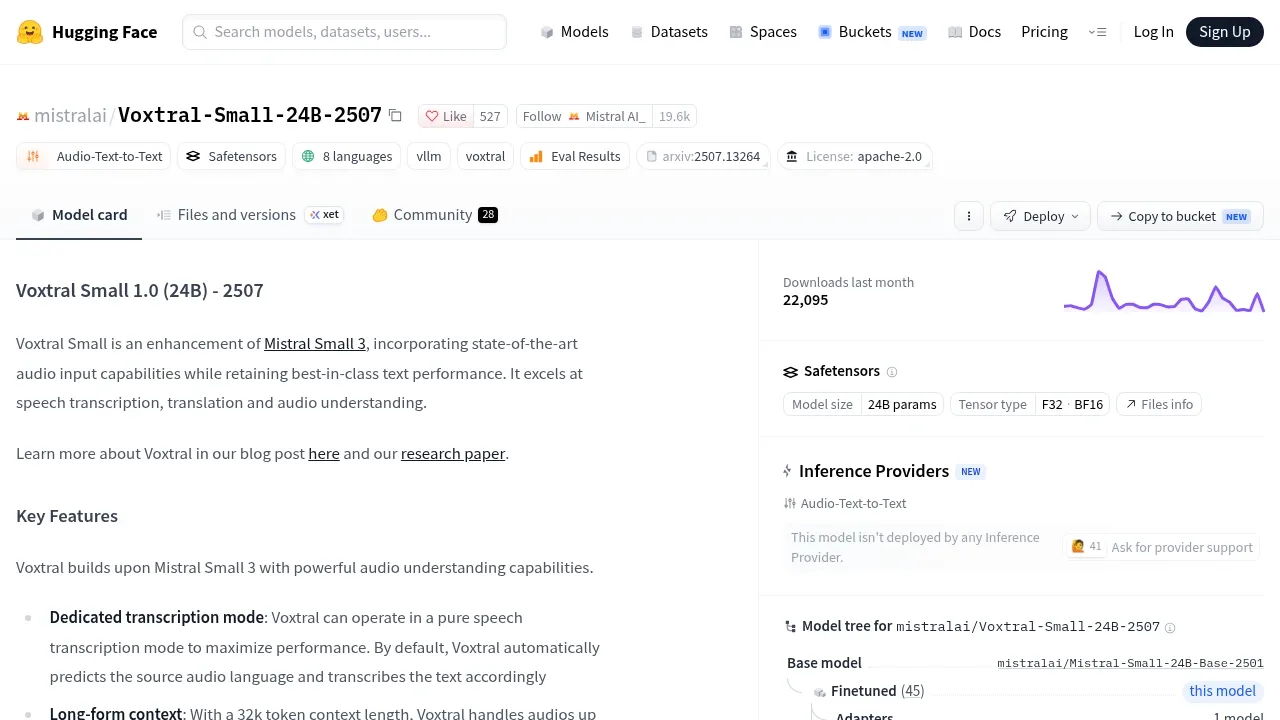
Voxtral Small is an audio and text model for developers building self-hosted speech applications. The separate mistral-inference library is archived and no longer maintained; this model runs with vLLM or Hugging Face Transformers.
- Transcription and translation: Transcribe speech with automatic source-language detection or translate audio content.
- Recording Q&A: Ask questions about audio and produce structured summaries within the same model, without a separate speech recognition model.
- Audio conversations: Include multiple recordings in a message and ask follow-up questions across conversation turns.
- Long recordings: Process up to 30 minutes of audio for transcription or 40 minutes for audio understanding.
Supported languages include English, Spanish, French, Portuguese, Hindi, German, Dutch and Italian. The model also accepts text-only conversations.
Voxtral Small is open source under Apache 2.0, with weights in Safetensors format. It supports offline inference and deployment behind a server you control, allowing local processing of recordings. The Small model requires about 55 GB of GPU memory at bf16 or fp16 precision. It doesn't support system prompts.
 Logotyper


