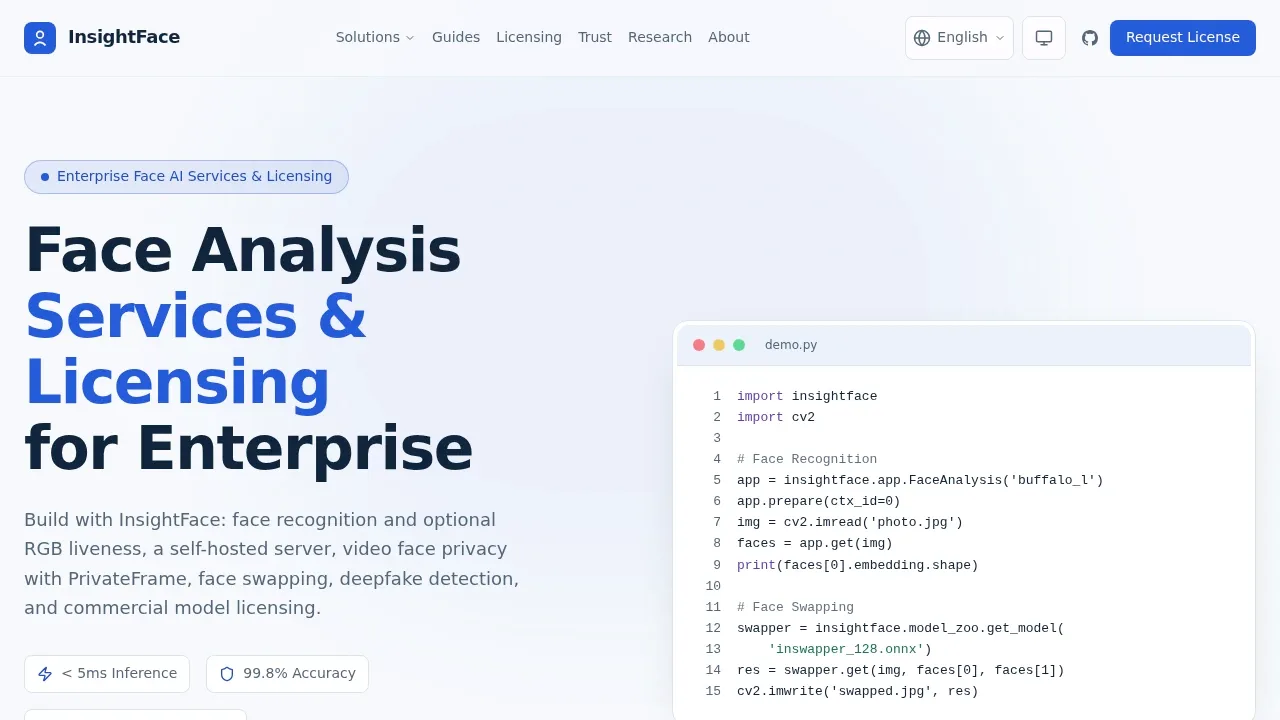
InsightFace is a face analysis toolkit for developers and teams building identity verification, access control, or face editing software. The code uses the MIT license. Its Python tools and self-hosted recognition server run inference on your own hardware. It also offers commercial models and API access for face swapping and deepfake detection.
InsightFace Server runs in a Linux x86_64 container with ONNX Runtime on CPU or NVIDIA GPU. A browser interface, REST API, and Python client cover face detection, comparison, enrollment, and person search. Optional RGB liveness checks assess faces before recognition. The server supports exact searches across enrolled identities and persistent RTSP camera monitoring, with SQLite for local storage.
PrivateFrame handles video face redaction on your device through a desktop app, CLI, or Python. It tracks faces, uses reference photos to select who stays visible, and exports blur or mosaic effects. Saved analysis lets you revise the redaction and render again without repeating face detection.
The Python package works with model packages such as buffalo_l and antelopev2 and supports CoreML, CUDA, and CPU execution. InspireFace provides a C/C++ SDK with anti-spoofing and liveness detection for Linux, Android, iOS, macOS, and embedded devices. Face swapping includes InSwapper-128 and a local NVIDIA GPU option for live streaming. Pretrained models are restricted to non-commercial academic research unless you obtain a commercial license; PrivateFrame also requires a commercial model license.
Claim this page with an email at insightface.ai. InsightFace gets the verified badge, and you can upgrade the listing to be featured on localhosted. Proud to be listed? Put our badge on your site.
Want more people to find InsightFace?Promote it
Something wrong or outdated on this page?
7.7KUpdated 5 days agoMIT
macOS · Windows · Linux · Docker · Web#Code execution#GGUF#Hugging Face integration
mistral.rs is an open source inference engine for running models on your own computer or self-hosted server. It's for developers building AI applications and people who want local chat, multimodal models and agent tools in the same runtime. The Rust project uses the MIT license.
23.2KUpdated 23 hours agoApache-2.0
macOS · Windows · Linux · iOS · Android · Web#OpenAI-compatible API
MLC LLM is an open-source compiler and deployment engine for developers who want to run language models on their own hardware or inside apps. Its main distinction is the range of devices it targets: the same underlying engine, MLCEngine, serves desktop, browser and mobile deployments. The project uses the Apache 2.0 license.
1.9KUpdated 3 weeks agoAGPL-3.0
macOS · Windows · Linux · Docker#Batch processing#Distributed execution#Hugging Face integration
77.4KUpdated 1 year agoMIT
macOS · Windows · Linux · Docker#GGUF#llama.cpp backend#OpenAI-compatible API
qualcomm/GenieXInference Libraries and Bindings
macOS · Windows · Linux#GGUF#Hugging Face integration#llama.cpp backend
10.9KUpdated 23 hours agoApache-2.0
macOS · Windows · Linux#Hugging Face integration#Multimodal input#ONNX
Sonar is a self-hosted inference engine for developers and teams serving Hugging Face-compatible language and multimodal models on their own hardware. Based on vLLM, it adds model and quantization formats, sampling methods, and deployment features. It's open source under AGPL-3.0.
GPT4All is a local AI chatbot for people who want to run language models on their own desktop or laptop and keep conversations on their machine. Its LocalDocs feature lets you ask questions about your own documents without sending them to a cloud service. It suits developers, teams and individuals who want control over their models and data.
Nexa SDK is an on-device AI inference framework for developers building applications that process text, images or audio on users' hardware. It runs models locally across CPUs, GPUs and NPUs, with a shared interface for different backends. Its scope includes language and vision models, speech recognition, speech synthesis and image generation.
OpenVINO is an Apache 2.0 licensed toolkit for developers who want to run AI models locally or serve them on their own infrastructure. It converts and optimizes models for inference, with support for x86 and ARM CPUs, Intel integrated and discrete GPUs, and Intel NPUs. Its runtime works on Linux, Windows and macOS.