
TTS WebUI
A self-hosted text-to-speech and music generation interface with audio editing tools, model extensions and an optional OpenAI-compatible speech API.
Alternative to:
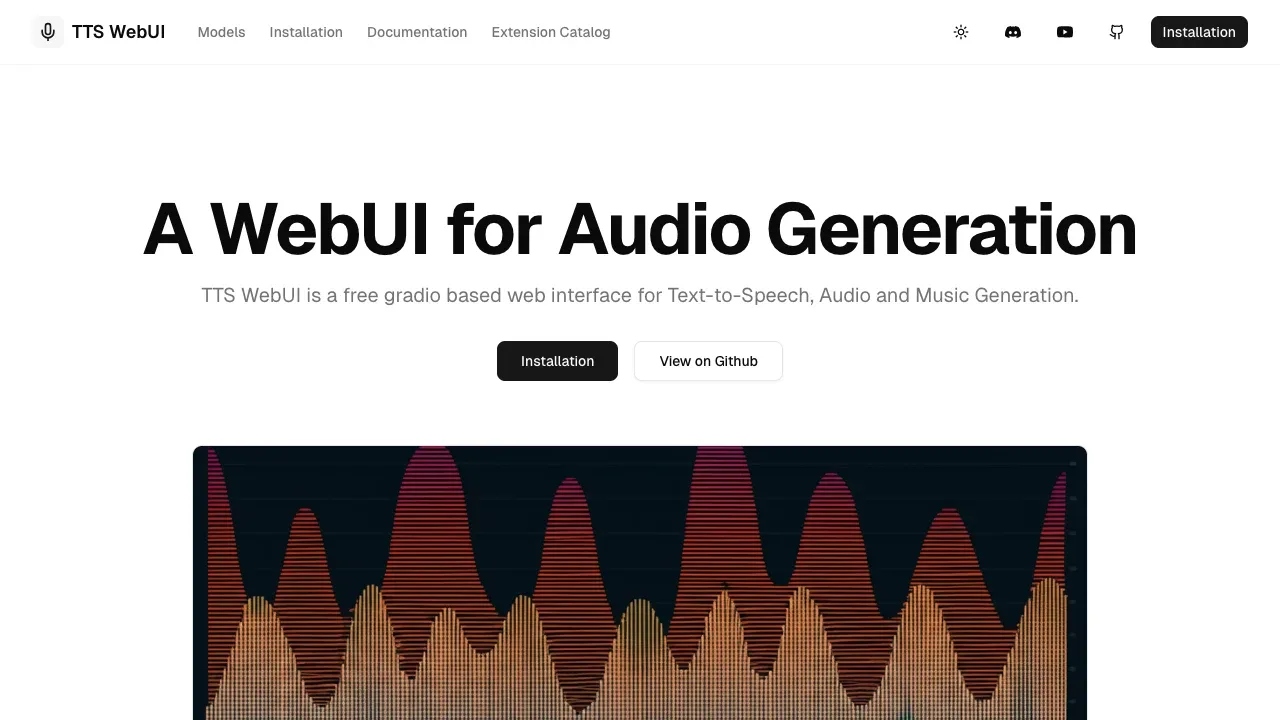
TTS WebUI is a self-hosted browser interface for people creating speech and music or processing audio with AI models. It brings these tasks into one place, with model choices for different kinds of audio work.
- Speech generation: Create spoken audio with models including Bark, Tortoise, StyleTTS2, XTTSv2 and F5-TTS.
- Music and audio generation: Generate music and sounds with MusicGen, MAGNeT, Stable Audio and ACE-Step.
- Audio processing: Convert voices with RVC, transcribe speech with Whisper, separate audio sources with Demucs or Audio Separator, and improve audio with Resemble Enhance.
- Chat app connections: An optional OpenAI-compatible speech API extension supplies generated speech to Silly Tavern, OpenWebUI and compatible clients; Text Generation WebUI has a separate integration.
The interface uses Gradio and React. Extensions add models and audio tools, though compatibility issues can occur when combining extensions.
The application is open source under the MIT license. Dependencies have their own licenses, including Apache 2.0 for Tortoise and LGPL for FFmpeg.
 Logotyper


