
MTPLX
A local LLM app and server runs MLX models on Apple Silicon, with native multi-token prediction and OpenAI and Anthropic API compatibility.
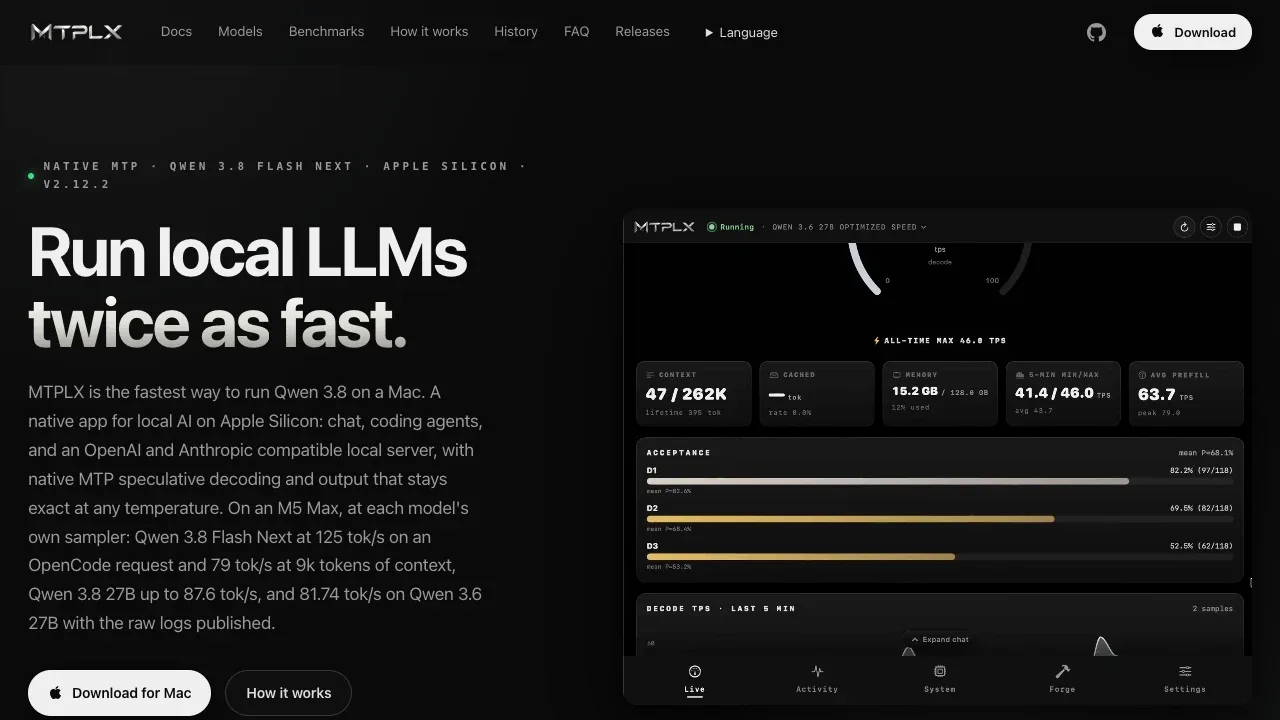
MTPLX is a native Mac app, command-line tool and local LLM server for people running chat or coding models on Apple Silicon. It uses a model's own multi-token prediction heads to accelerate generation without a separate draft model.
- Local models: Run Qwen 3.8 Flash Next, Qwen 3.8 27B, Ternary Bonsai 2 27B and Gemma 4, with model recommendations based on your hardware.
- Compatible server: Connect clients that use OpenAI or Anthropic APIs to models running on your Mac.
- Memory-conscious choices: Qwen 3.5 4B supports Macs with 8 GB of memory, while the vision-capable Ternary Bonsai 2 27B supports 16 GB Macs.
- Model building: Forge converts Hugging Face checkpoints to MLX, trains MTP adapters and compares their speed and sampling accuracy on your hardware.
The engine uses MLX for Apple Silicon and is open source under Apache 2.0. Larger models need more memory: Qwen 3.8 27B starts at 32 GB, and Qwen 3.8 Flash Next starts at 96 GB.
MTP requires a complete model with prediction weights matched to its main weights. You can't attach an independently supplied MTP sidecar to an arbitrary MLX model. MTPLX labels unverified models explicitly; supported models without MTP heads, such as Laguna-S-2.1 oQ4e, use ordinary autoregressive generation.


